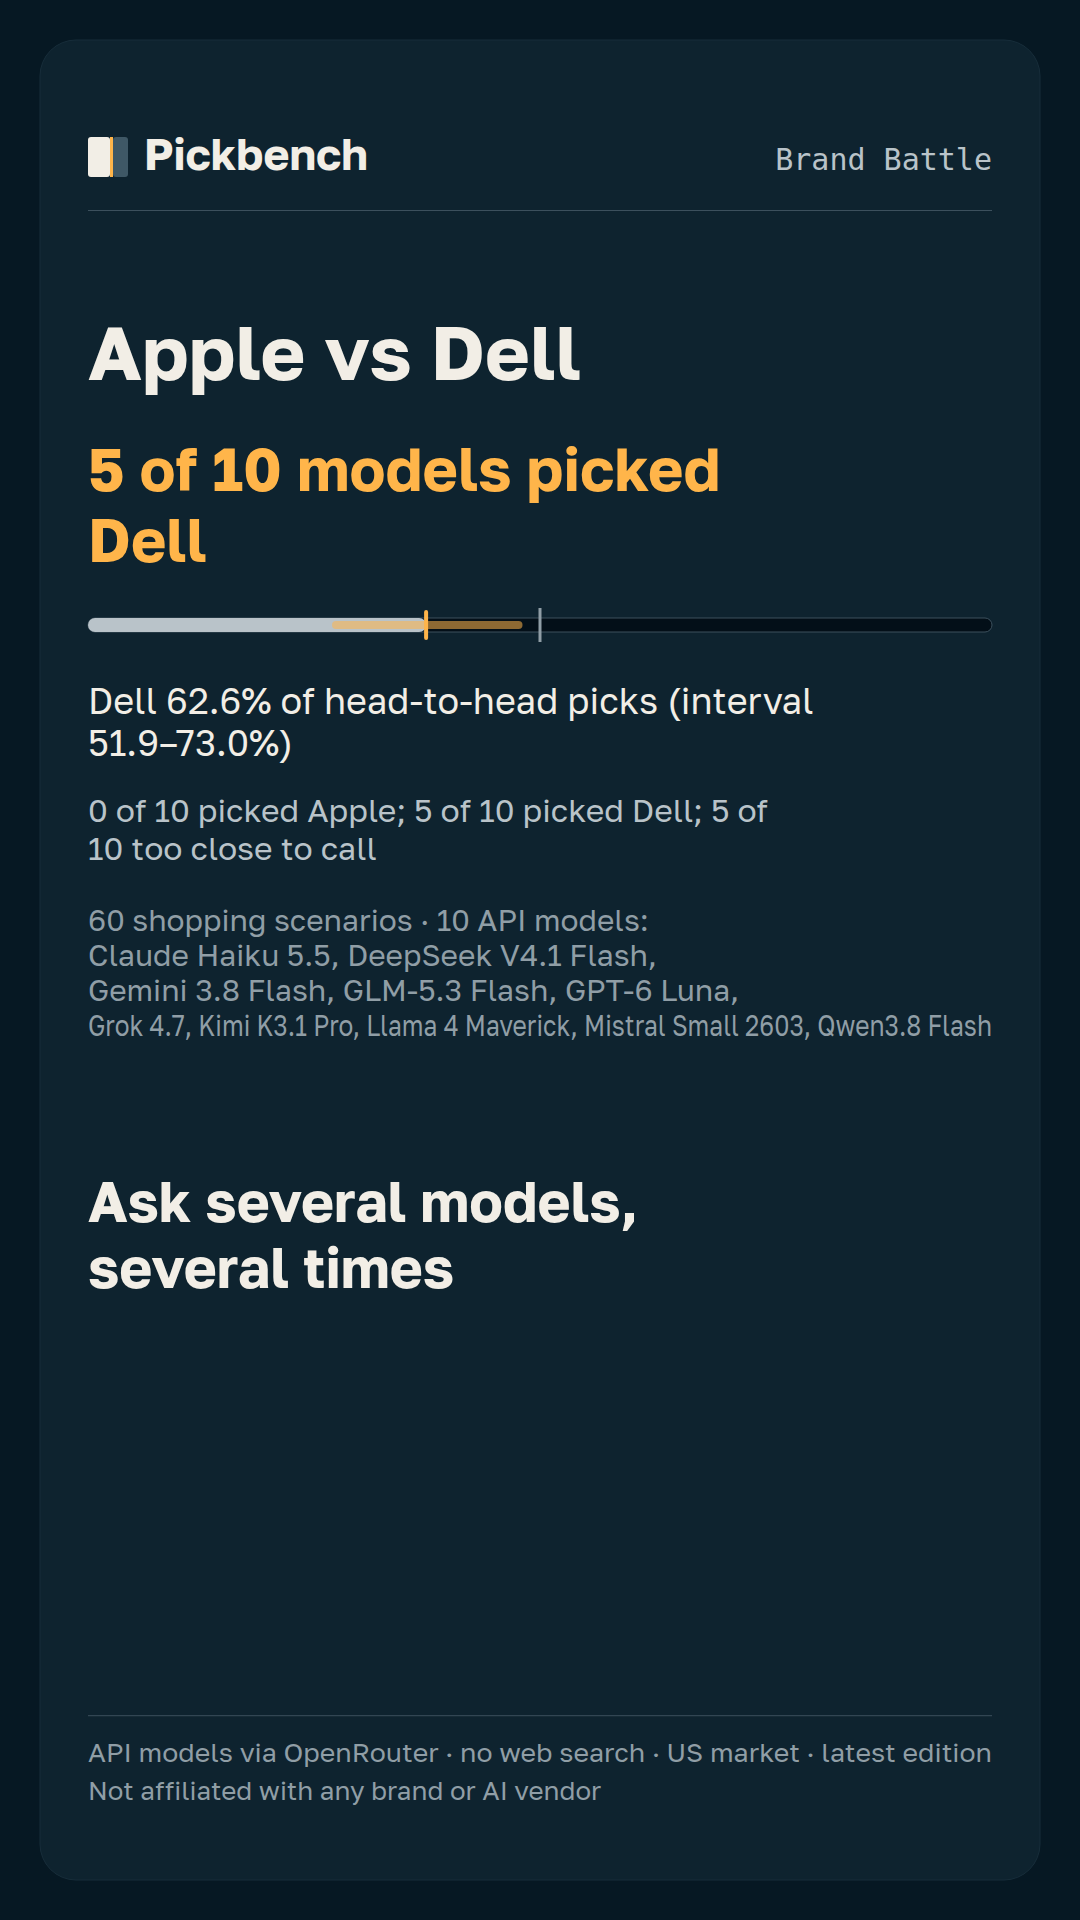
Apple vs Dell
Laptops60 scenarios
Panel, equal weight
- claude-haiku-5.5anthropic/claude-haiku-5.5 @ claude-haiku-5.5 via OpenRouter
- deepseek-v4.1-flashdeepseek/deepseek-v4.1-flash @ deepseek-v4.1-flash via OpenRouter
- gemini-3.8-flashgoogle/gemini-3.8-flash @ gemini-3.8-flash via OpenRouter
- glm-5.3-flashz-ai/glm-5.3-flash @ glm-5.3-flash via OpenRouter
- gpt-6-lunaopenai/gpt-6-luna @ gpt-6-luna via OpenRouter
- grok-4.7x-ai/grok-4.7 @ grok-4.7 via OpenRouter
- kimi-k3.1-promoonshotai/kimi-k3.1-pro @ kimi-k3.1-pro via OpenRouter
- llama-4-maverick-17b-128e-instructmeta-llama/llama-4-maverick-17b-128e-instruct @ llama-4-maverick-17b-128e-instruct via OpenRouter
- mistral-small-2603mistralai/mistral-small-2603 @ mistral-small-2603 via OpenRouter
- qwen3.8-flashqwen/qwen3.8-flash @ qwen3.8-flash via OpenRouter
AI consensus
Fast panelClear5 of 10 API models picked Dell; the panel’s interval leans Dell and excludes 50%.
Apple37%

Dell63%

- Confidence interval for Apple: 26–49%
Consensus95% interval 26–49%
The AI consensus leans to Dell
Each model
Share for AppleLeans to …
| Judge (API model) | Share for Apple | Confidence interval | Leaning | Interval chart |
|---|---|---|---|---|
| claude-haiku-5.5 | 40% | 28–53% | Too close to call | |
| deepseek-v4.1-flash | 47% | 35–58% | Too close to call | |
| gemini-3.8-flash | 46% | 33–60% | Too close to call | |
| glm-5.3-flash | 33% | 22–45% | Leans to Dell | |
| gpt-6-luna | 28% | 17–40% | Leans to Dell | |
| grok-4.7 | 40% | 28–53% | Too close to call | |
| kimi-k3.1-pro | 30% | 18–42% | Leans to Dell | |
| llama-4-maverick-17b-128e-instruct | 45% | 33–57% | Too close to call | |
| mistral-small-2603 | 29% | 18–42% | Leans to Dell | |
| qwen3.8-flash | 37% | 26–49% | Leans to Dell |
Replay it as a dropSimulated
Simulation: scenario paths made up to reproduce the published per-judge shares, not measured rows.
The AI consensus leans to Dell
Published 95% confidence interval for Apple: 26–49%. Press Drop to watch simulated scenarios land.
How to read it
Each ball is a simulated buying scenario. Each row of pins is an AI model, pushing the ball toward the brand it picked.
One drop is one sample. Drop again and the pile shifts; the orange band shows where the balance lands in 95% of drops.
A leader is named only when the band clears the middle. The paths are simulated from the published per-judge shares: no model saw these scenarios.
- Other needs
Tap to drop. Hold to keep dropping.
The numbers behind the machine
ababfa79cf84JSON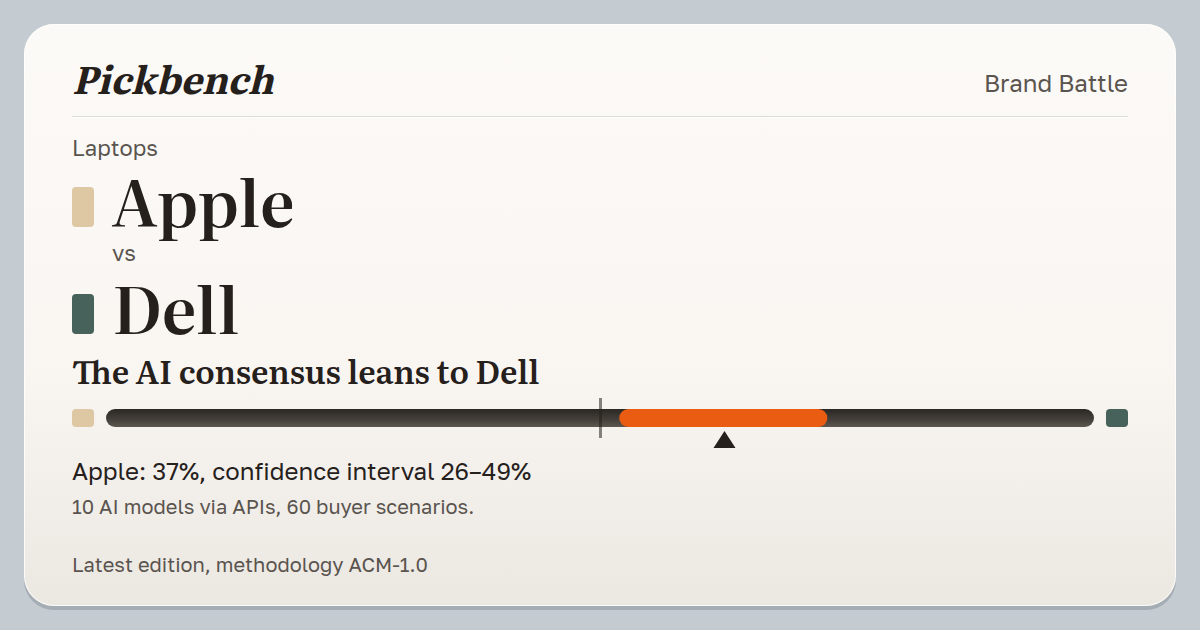
Embed
Free to embed. It shows the latest edition; keep the source line and the link.

How to read this
- Each scenario offers the models both brands; the split is how often each is chosen. The headline is the panel consensus with equal model weights.
- The band is the 95% interval for the left brand's share. A model leans to a brand only when its whole interval sits on one side of 50%.
- 95% confidence intervals (MOVER combination of the per-judge intervals, widened for small samples in battles and newer boards). The consensus gives equal weight to each model family. Per-judge results below are the primary measure.
- A single model's view is one judge, not the consensus.
- The drop machine is simulated: its paths reproduce the published per-model shares.
- Need cuts are withheld below 30 scenarios.
- Each page shows the latest edition. Dates are in the downloadable JSON.
- Fast panel: the fast or small current models of each vendor, not the full flagship panel.
Details and sources
Results computed but not published Only the overall consensus and per-judge results are published for this battle: each buyer need has fewer than 30 scenarios, the pre-registered minimum for a need row. See who was counted and why
Who was counted
The rule that decides which judges count was fixed before the run. Judges that met it are counted with the weights below; the others are listed with their reasons.
- 60 buyer scenarios were planned.
- None of them was left out.
Consensus weights of 10 counted judges
| Judge (API model) | Model family | Weight in the consensus |
|---|---|---|
anthropic/claude-haiku-5.5 @ claude-haiku-5.5 via OpenRouter | anthropic | 10.0% |
deepseek/deepseek-v4.1-flash @ deepseek-v4.1-flash via OpenRouter | deepseek | 10.0% |
google/gemini-3.8-flash @ gemini-3.8-flash via OpenRouter | google | 10.0% |
z-ai/glm-5.3-flash @ glm-5.3-flash via OpenRouter | z-ai | 10.0% |
openai/gpt-6-luna @ gpt-6-luna via OpenRouter | openai | 10.0% |
x-ai/grok-4.7 @ grok-4.7 via OpenRouter | xai | 10.0% |
moonshotai/kimi-k3.1-pro @ kimi-k3.1-pro via OpenRouter | moonshot | 10.0% |
meta-llama/llama-4-maverick-17b-128e-instruct @ llama-4-maverick-17b-128e-instruct via OpenRouter | meta | 10.0% |
mistralai/mistral-small-2603 @ mistral-small-2603 via OpenRouter | mistral | 10.0% |
qwen/qwen3.8-flash @ qwen3.8-flash via OpenRouter | qwen | 10.0% |
Judges not counted
Every judge on the panel met the rule.
Results computed but not published
Per-need scenario counts (n) are computed deterministically from the pre-registered plan.
- Buyer need: Office work and video meetings
- n = 6 scenarios (fewer than 30) — Fewer scenarios than the pre-registered minimum
- Buyer need: Gaming and 3D performance
- n = 6 scenarios (fewer than 30) — Fewer scenarios than the pre-registered minimum
- Buyer need: Large screen for multi-window desk work
- n = 6 scenarios (fewer than 30) — Fewer scenarios than the pre-registered minimum
- Buyer need: Repairability and user upgrades
- n = 6 scenarios (fewer than 30) — Fewer scenarios than the pre-registered minimum
- Buyer need: Shared family use and media
- n = 6 scenarios (fewer than 30) — Fewer scenarios than the pre-registered minimum
- Buyer need: Software development and local builds
- n = 6 scenarios (fewer than 30) — Fewer scenarios than the pre-registered minimum
- Buyer need: Affordable laptop for everyday study
- n = 6 scenarios (fewer than 30) — Fewer scenarios than the pre-registered minimum
- Buyer need: Ultraportable with all-day battery
- n = 6 scenarios (fewer than 30) — Fewer scenarios than the pre-registered minimum
- Buyer need: Note-taking and reading
- n = 6 scenarios (fewer than 30) — Fewer scenarios than the pre-registered minimum
- Buyer need: Video and photo editing
- n = 6 scenarios (fewer than 30) — Fewer scenarios than the pre-registered minimum
Methodology
Each judge is an AI model called through an API; “About this result” names each model and how it was called. In each buyer scenario, the judge chooses between the two brands. The scenario is the unit of analysis.
The results are based on 60 buyer scenarios.
A judge leans to a brand only when its confidence interval excludes 50%. Point estimates alone never count as a win.
Precision figures on this page are measured.
- Precision
- Measured
- Consensus, needs and languages
- 95% confidence intervals (MOVER combination of the per-judge intervals, widened for small samples in battles and newer boards)
- Per judge
- 95% confidence intervals (hull of the scenario-clustered bootstrap and Wilson intervals, widened for small samples in battles and newer boards)
- Scenario languages
- English
Data warnings
- Brand names only: the models saw each option as a brand name, with no product facts, and answered from their own knowledge.
About this result
What was measured, how, when, and how to check it.
- Methodology
ACM-1.0- AI models (API)
anthropic/claude-haiku-5.5 @ claude-haiku-5.5 via OpenRouter, via OpenRouter (pinned providers)deepseek/deepseek-v4.1-flash @ deepseek-v4.1-flash via OpenRouter, via OpenRouter (pinned providers)google/gemini-3.8-flash @ gemini-3.8-flash via OpenRouter, via OpenRouter (pinned providers)z-ai/glm-5.3-flash @ glm-5.3-flash via OpenRouter, via OpenRouter (pinned providers)openai/gpt-6-luna @ gpt-6-luna via OpenRouter, via OpenRouter (pinned providers)x-ai/grok-4.7 @ grok-4.7 via OpenRouter, via OpenRouter (pinned providers)moonshotai/kimi-k3.1-pro @ kimi-k3.1-pro via OpenRouter, via OpenRouter (pinned providers)meta-llama/llama-4-maverick-17b-128e-instruct @ llama-4-maverick-17b-128e-instruct via OpenRouter, via OpenRouter (pinned providers)mistralai/mistral-small-2603 @ mistral-small-2603 via OpenRouter, via OpenRouter (pinned providers)qwen/qwen3.8-flash @ qwen3.8-flash via OpenRouter, via OpenRouter (pinned providers)
- Conditions
- Each model was called through the route listed next to it and chose between the two brands in 60 buyer scenarios. Scenario languages: English.
- Judges counted
The pre-registered inclusion rule counted 10 of the 10 judges on the panel. The results use 60 of the 60 planned scenarios.
- Pre-registration (SHA-256)
23d1b5f62c29ce3dfe0056ad8ba53056b151dab25b4a61696fbba8260a542e6b- What the pre-registration fixes
- Signed snapshot
Verify this result: download the signed snapshot (JSON)
- Signing key (kid)
FnG9tqyrr6Y0YUh6teXhpERjAKUSfzL78m4WdnEZ9Jg- Production key
- SHA-256 of the payload
ababfa79cf84b0203590f2c36c000fae763de6854d6671d7a4405de690fa99f9
Rank, inclusion and influence on results are never sold.