Michelin vs Goodyear
Tires60 scenarios
Panel, equal weight
- Claude Haiku 5.5anthropic/claude-haiku-5.5
- DeepSeek V4.1 Flashdeepseek/deepseek-v4.1-flash
- Gemini 3.8 Flashgoogle/gemini-3.8-flash
- GLM-5.3 Flashz-ai/glm-5.3-flash
- GPT-6 Lunaopenai/gpt-6-luna
- Grok 4.7x-ai/grok-4.7
- Kimi K3.1 Promoonshotai/kimi-k3.1-pro
- Llama 4 Maverickmeta-llama/llama-4-maverick-17b-128e-instruct
- Mistral Small 2603mistralai/mistral-small-2603
- Qwen3.8 Flashqwen/qwen3.8-flash
The answer
ClearFast panel
Michelin
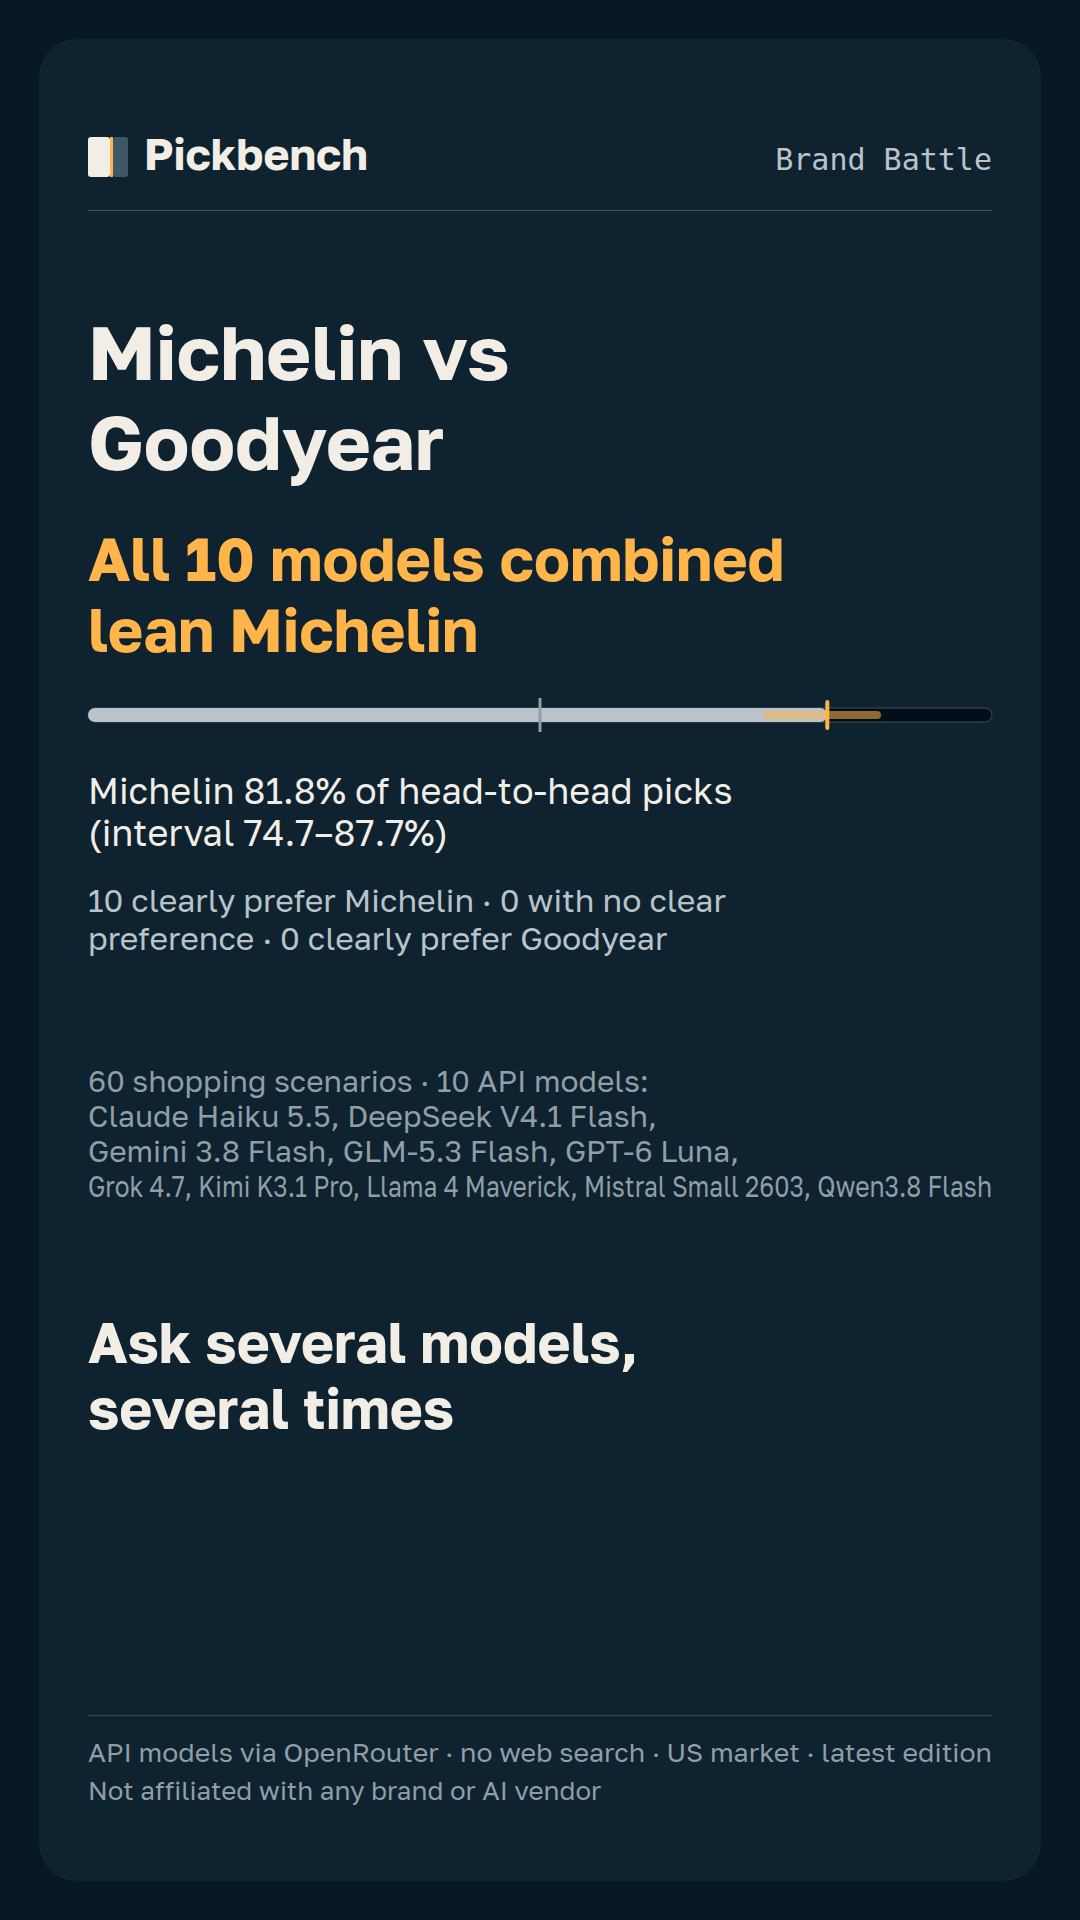
Michelin 82% · Goodyear 18% — all 10 models combined
10 clearly prefer Michelin · 0 with no clear preference · 0 clearly prefer Goodyear · all 10 models count in the overall result
95% interval for Michelin: 74–88%
Detailseach model, intervals, conditions
All models combined
Fast panelClearAll 10 models combined lean Michelin (the interval excludes 50%); on their own: 10 clearly prefer Michelin · 0 with no clear preference · 0 clearly prefer Goodyear.
Michelin82%

Goodyear18%

- Confidence interval for Michelin: 74–88%
Consensus95% interval 74–88%
Each model
Share for the brand named in each row, with its interval
Bar: Michelin from the left, Goodyear from the right; dashed line = 50%.
| Judge (API model) | Brand and share | Confidence interval | Leaning | Interval chart |
|---|---|---|---|---|
| Claude Haiku 5.5 | Michelin: 85% | 76–93% | Clear preference | |
| DeepSeek V4.1 Flash | Michelin: 70% | 59–81% | Clear preference | |
| Gemini 3.8 Flash | Michelin: 81% | 69–91% | Clear preference | |
| GLM-5.3 Flash | Michelin: 89% | 78–96% | Clear preference | |
| GPT-6 Luna | Michelin: 68% | 62–75% | Clear preference | |
| Grok 4.7 | Michelin: 83% | 71–92% | Clear preference | |
| Kimi K3.1 Pro | Michelin: 76% | 65–85% | Clear preference | |
| Llama 4 Maverick | Michelin: 89% | 82–94% | Clear preference | |
| Mistral Small 2603 | Michelin: 88% | 79–95% | Clear preference | |
| Qwen3.8 Flash | Michelin: 89% | 83–94% | Clear preference |
Replay it as a dropSimulated
Simulation: scenario paths made up to reproduce the published per-judge shares, not measured rows.
The AI consensus leans to Michelin
Published 95% confidence interval for Michelin: 74–88%. Press Drop to watch simulated scenarios land.
How to read it
Each ball is a simulated buying scenario. Each row of pins is an AI model, pushing the ball toward the brand it picked.
One drop is one sample. Drop again and the pile shifts; the orange band shows where the balance lands in 95% of drops.
A leader is named only when the band clears the middle. The paths are simulated from the published per-judge shares: no model saw these scenarios.
- Other needs
Tap to drop. Hold to keep dropping.
The numbers behind the machine
e376e5da4f4fJSON
Embed
Free to embed. It shows the latest edition; keep the source line and the link.
How this was measured · verify
How to read
The share is how often the models chose each brand, with its 95% interval. A brand leads only when its whole interval is above 50%, for all models combined and for each model on its own; otherwise it is too close to call.
Each page shows the latest edition. Dates are in the downloadable JSON.
Who was counted
- The pre-registered inclusion rule counted 10 of the 10 judges on the panel.
- The results use 60 of the 60 planned scenarios.
- Every judge on the panel met the rule.
Consensus weights of 10 counted judges
| Judge (API model) | Model family | Weight in the consensus |
|---|---|---|
| Claude Haiku 5.5 | Anthropic | 10.0% |
| DeepSeek V4.1 Flash | DeepSeek | 10.0% |
| Gemini 3.8 Flash | 10.0% | |
| GLM-5.3 Flash | Z.ai | 10.0% |
| GPT-6 Luna | OpenAI | 10.0% |
| Grok 4.7 | xAI | 10.0% |
| Kimi K3.1 Pro | Moonshot AI | 10.0% |
| Llama 4 Maverick | Meta | 10.0% |
| Mistral Small 2603 | Mistral AI | 10.0% |
| Qwen3.8 Flash | Qwen | 10.0% |
Need-level results
Need-level results are not published: 6 scenarios per need, below the pre-registered minimum of 30.
10 buyer needs
- Load support for heavy crossovers and EVs
- Grip in heavy rain
- High-mileage highway commuting
- All-terrain durability for pickups and SUVs
- Quiet and comfortable ride
- Sporty cornering and steering
- Stable when towing or fully loaded
- Value replacement set
- Winter and snow traction
- Year-round all-season use
Methodology
Each judge is an AI model called through an API; “About this result” names each model and how it was called. In each buyer scenario, the judge chooses between the two brands. The scenario is the unit of analysis.
- Version
ACM-1.0- Precision
- Measured
- Consensus, needs and languages
- 95% confidence intervals (MOVER combination of the per-judge intervals, widened for small samples in battles and newer boards). The consensus gives equal weight to each model family. The per-judge results in “Each model” are the primary measure.
- Per judge
- 95% confidence intervals (hull of the scenario-clustered bootstrap and Wilson intervals, widened for small samples in battles and newer boards). A single model's view is one judge, not the consensus.
- Panel
- Fast panel: the fast or small current models of each vendor, not the full flagship panel.
Data warnings
- Brand names only: the models saw each option as a brand name, with no product facts, and answered from their own knowledge.
About this result
- AI models (API)
- Claude Haiku 5.5
- DeepSeek V4.1 Flash
- Gemini 3.8 Flash
- GLM-5.3 Flash
- GPT-6 Luna
- Grok 4.7
- Kimi K3.1 Pro
- Llama 4 Maverick
- Mistral Small 2603
- Qwen3.8 Flash
Every model was called via OpenRouter (pinned providers).
- Conditions
- Each model chose between the two brands in 60 buyer scenarios. Scenario languages: English.
- Pre-registration (SHA-256)
ee692eb57b5e…What the pre-registration fixes- Signed snapshot
Verify this result: download the signed snapshot (JSON)
- Signing key (kid)
FnG9tqyrr6Y0…· Production key- SHA-256 of the payload
e376e5da4f4f…
Rank, inclusion and influence on results are never sold.