Pick Drift
Same question, three asks: does the AI model's top pick change?
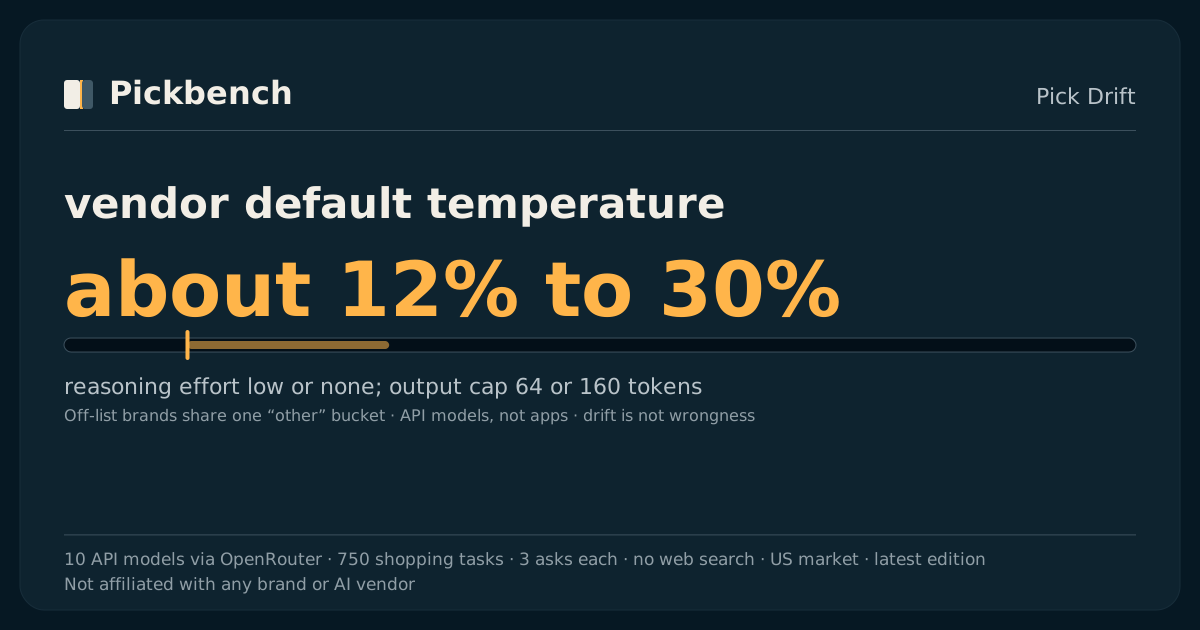
Vendor default temperature
about 12–30%
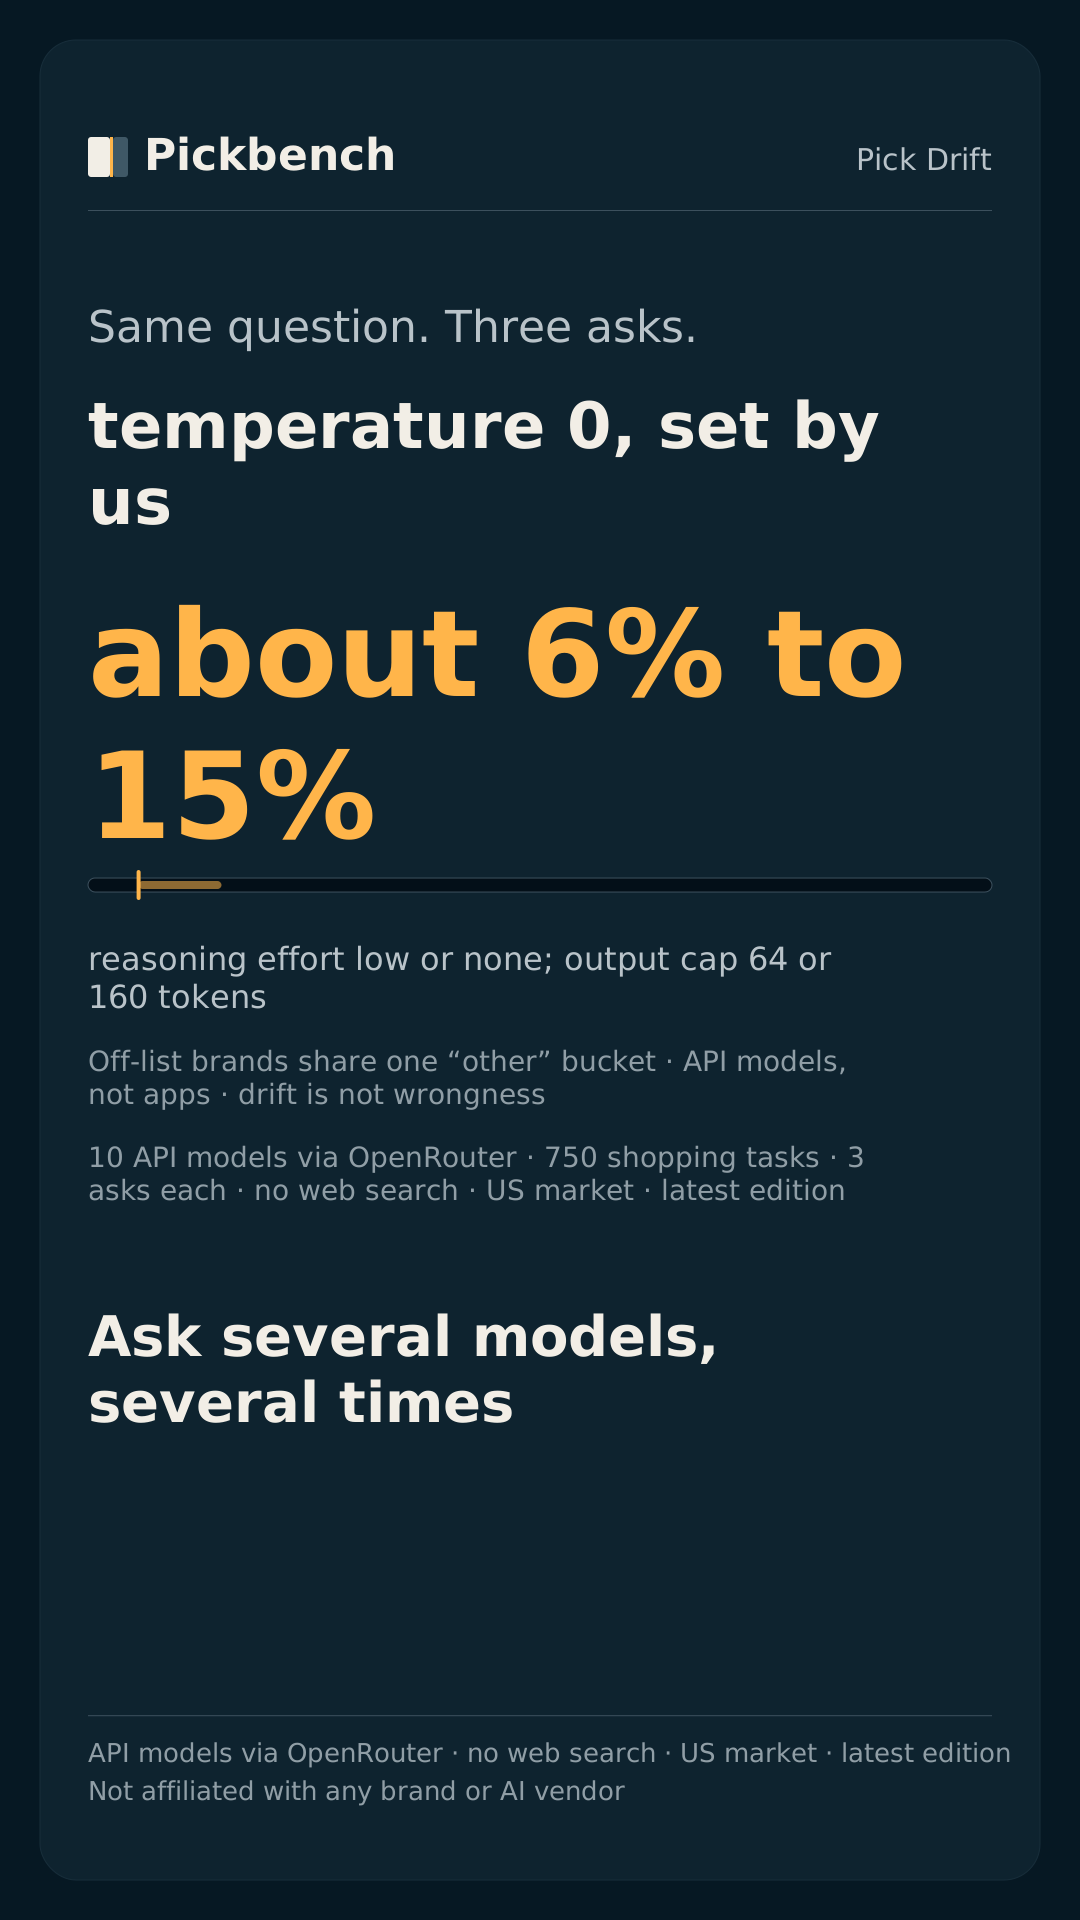
Temperature 0, set by us
about 6–15%
Every model, by setting
Vendor default temperature
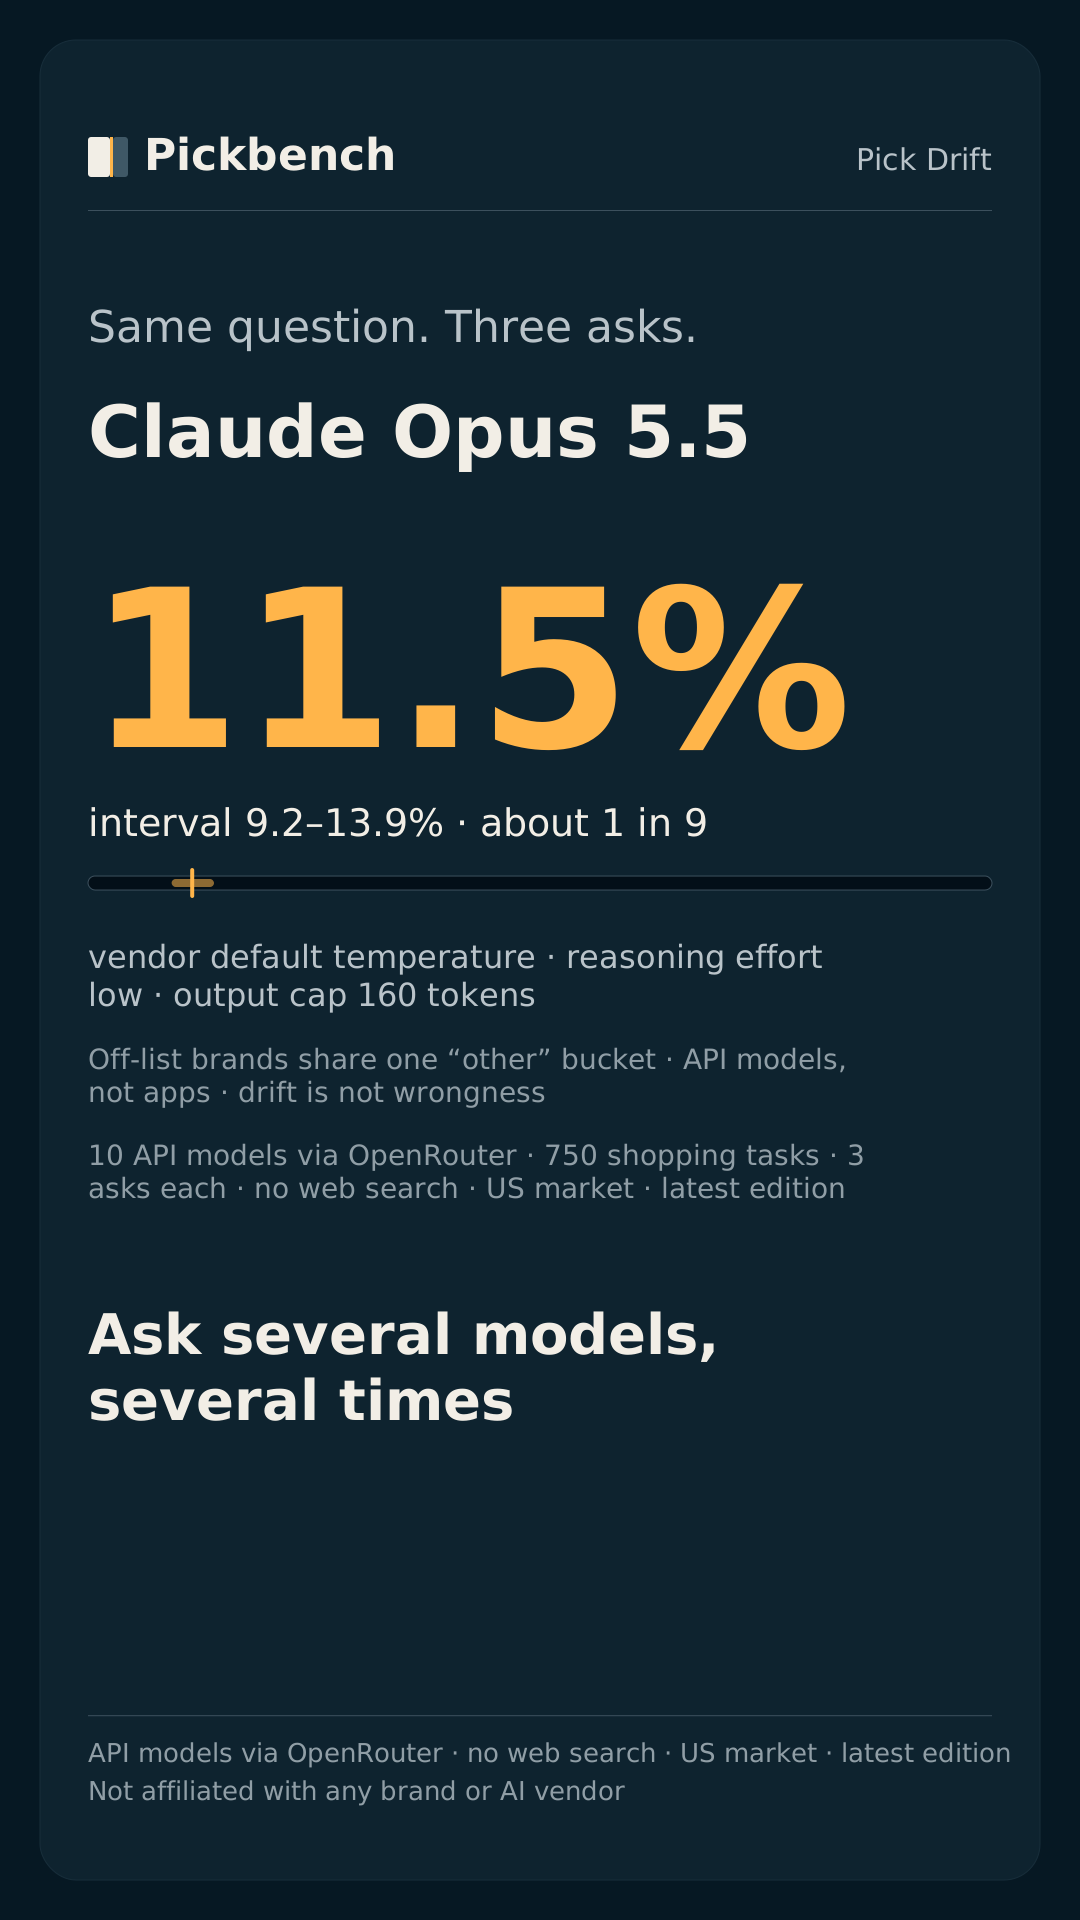
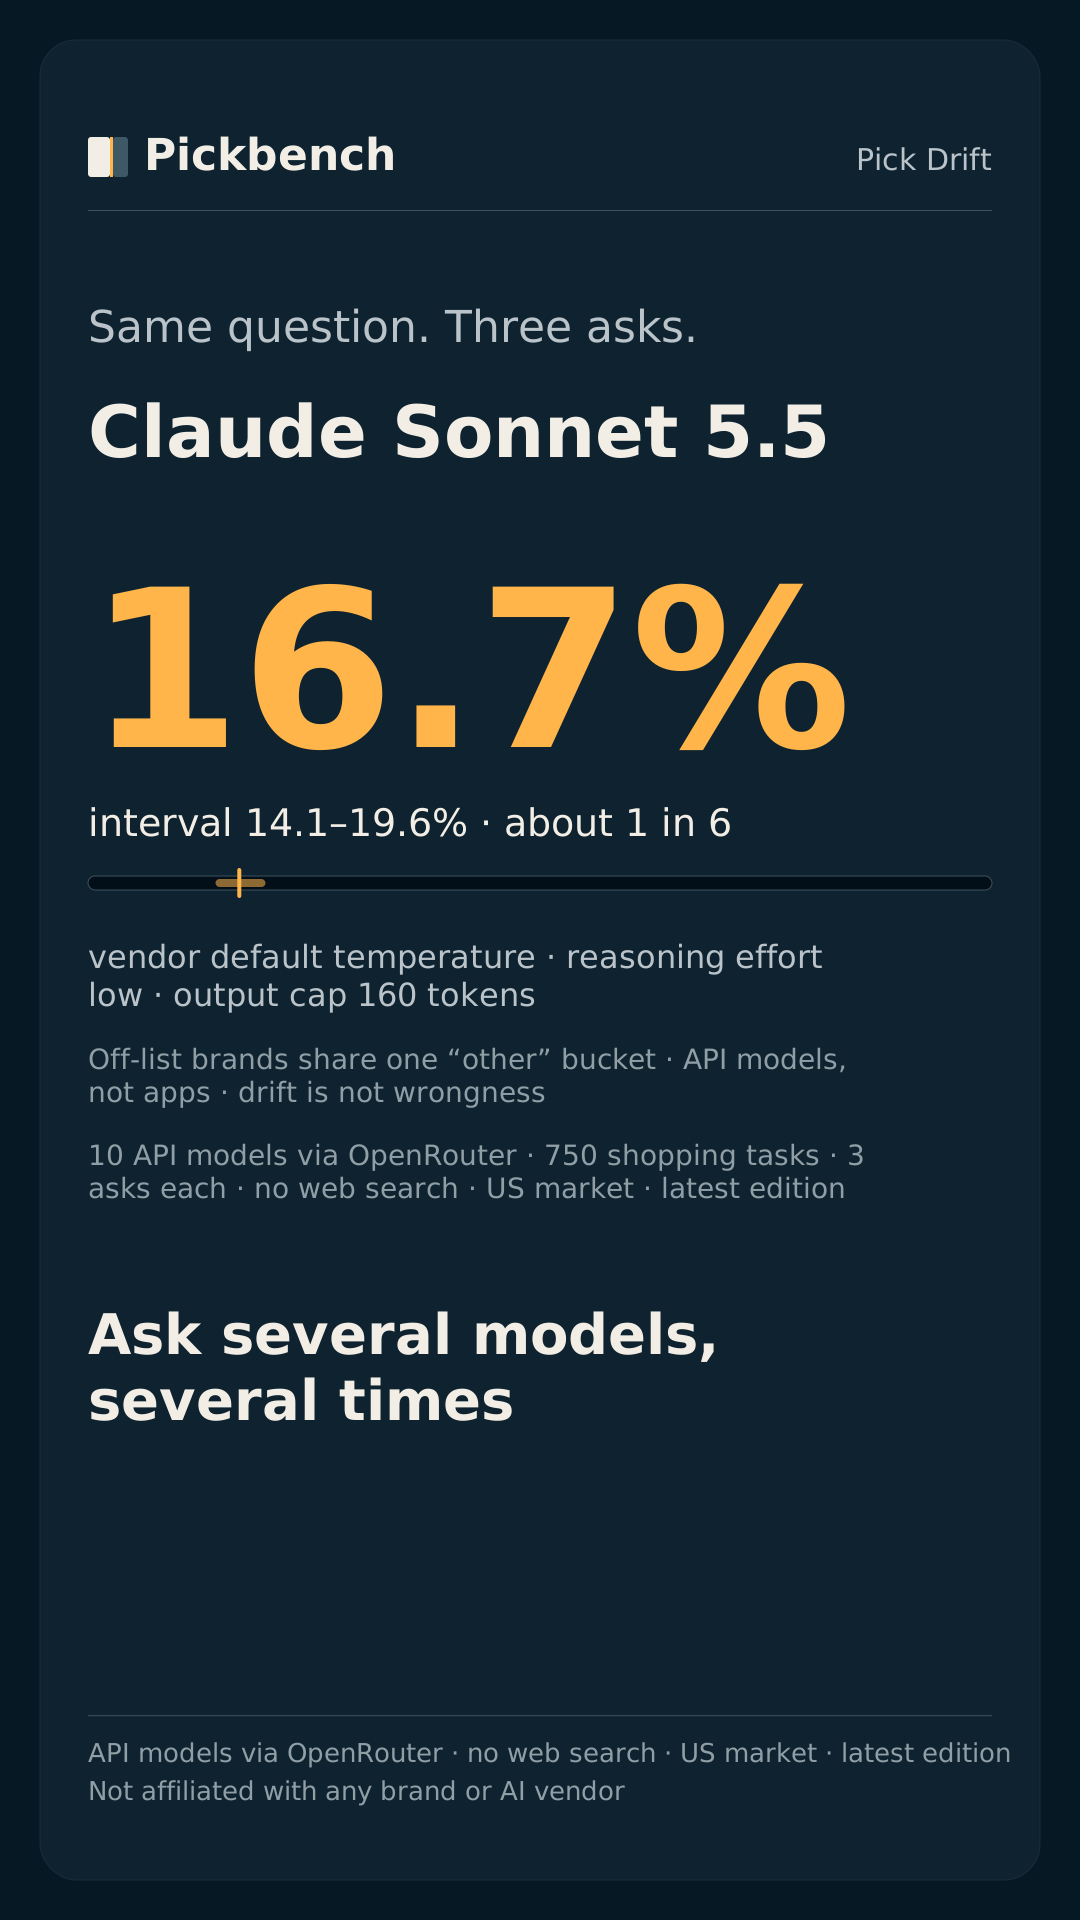
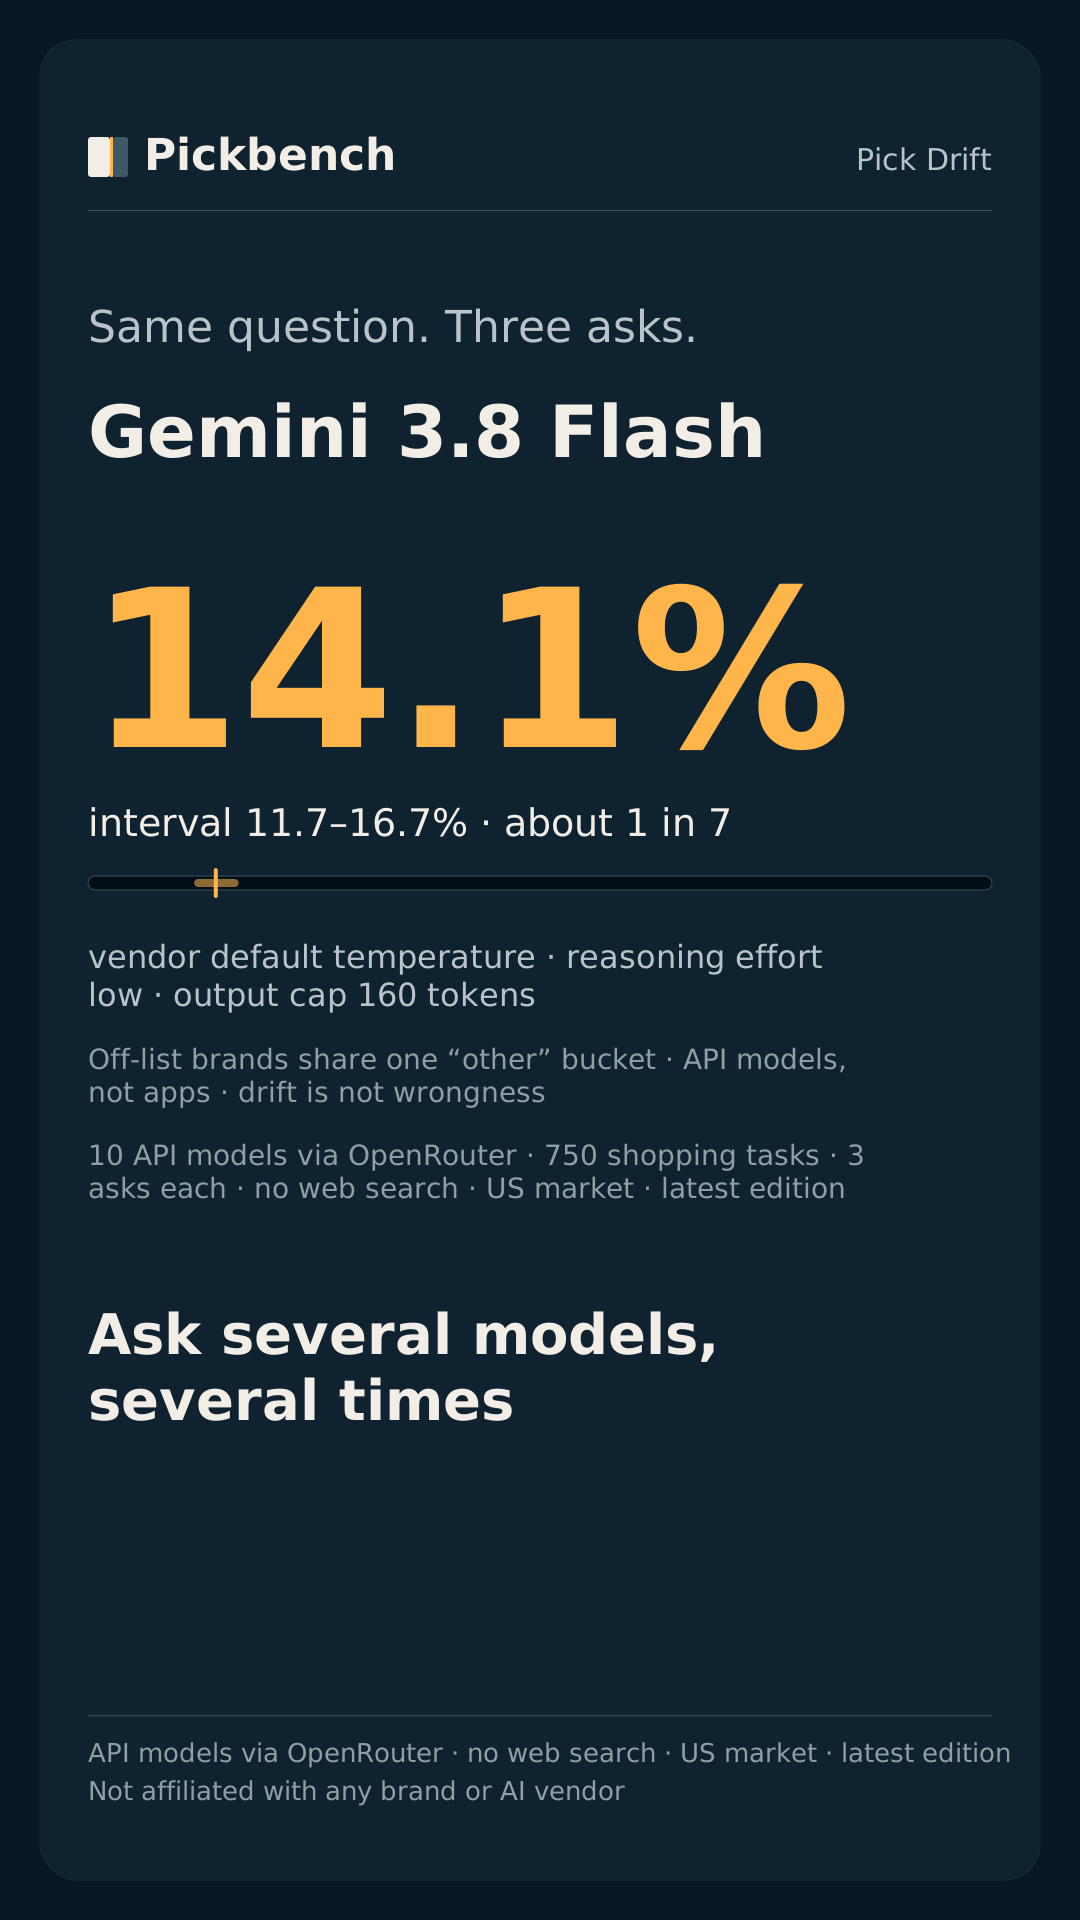
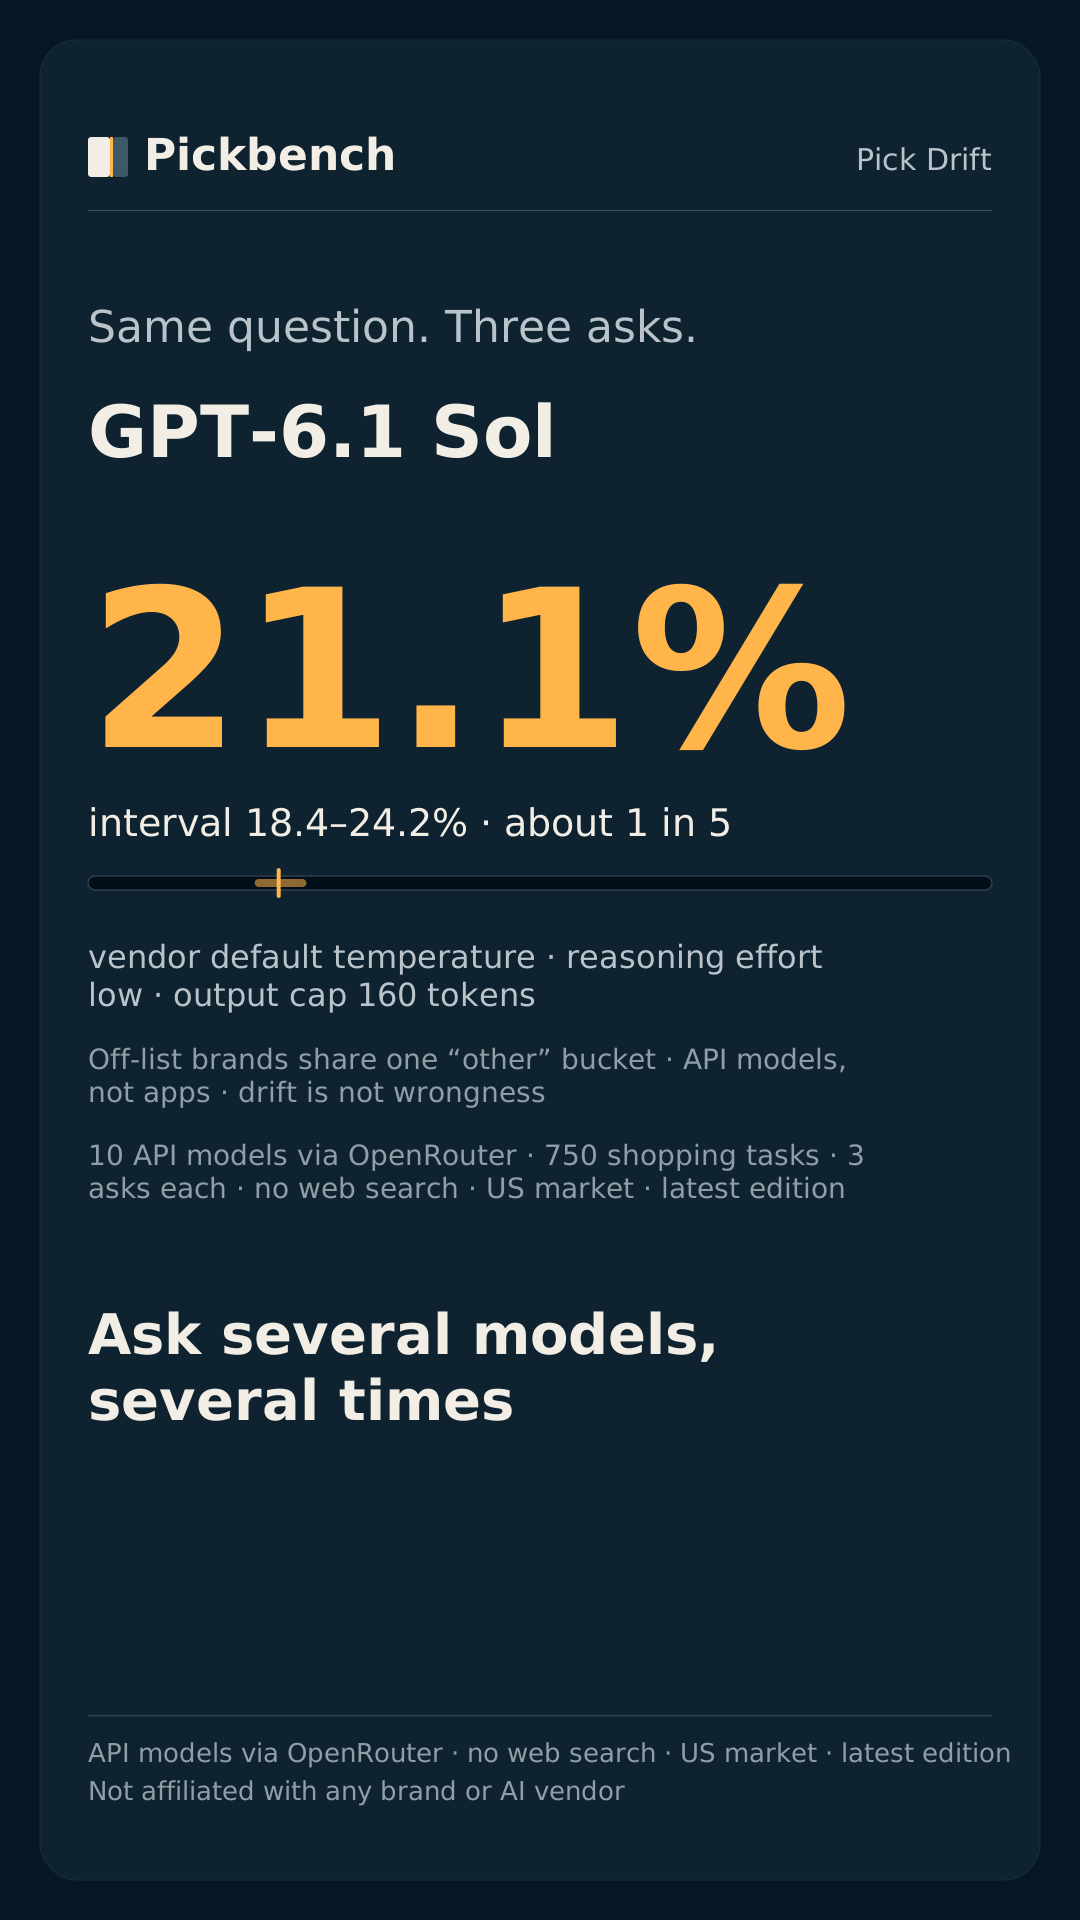
Reasoning effort low · output cap 160 tokens
- Claude Opus 5.511.5%9.2–13.9%
Details
about 1 in 9 · Two asks differ 7.9% (6.4–9.5%) - Claude Sonnet 5.516.7%14.1–19.6%
Details
about 1 in 6 · Two asks differ 11.2% (9.5–13.1%) - Gemini 3.8 Flash14.1%11.7–16.7%
Details
about 1 in 7 · Two asks differ 9.6% (8.0–11.3%) - GPT-6.1 Sol21.1%18.4–24.2%
Details
about 1 in 5 · Two asks differ 14.5% (12.6–16.6%)
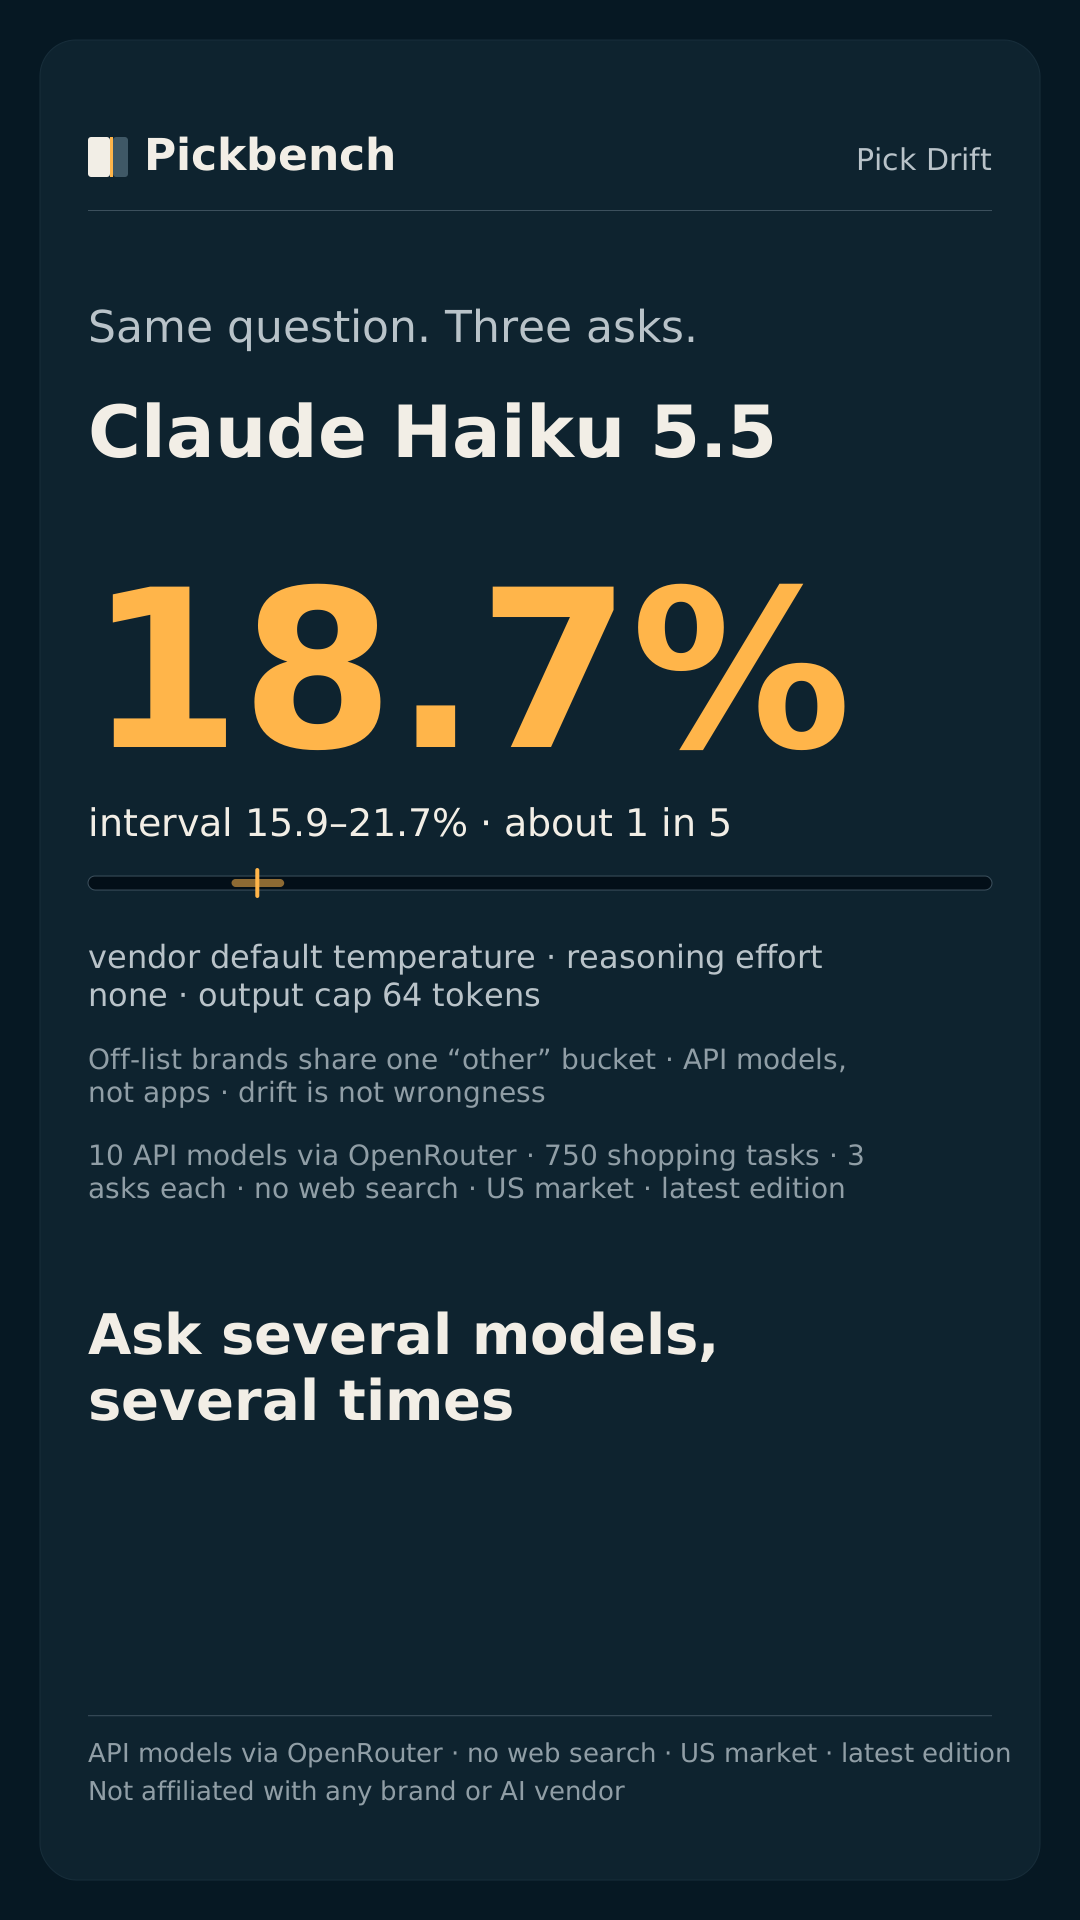
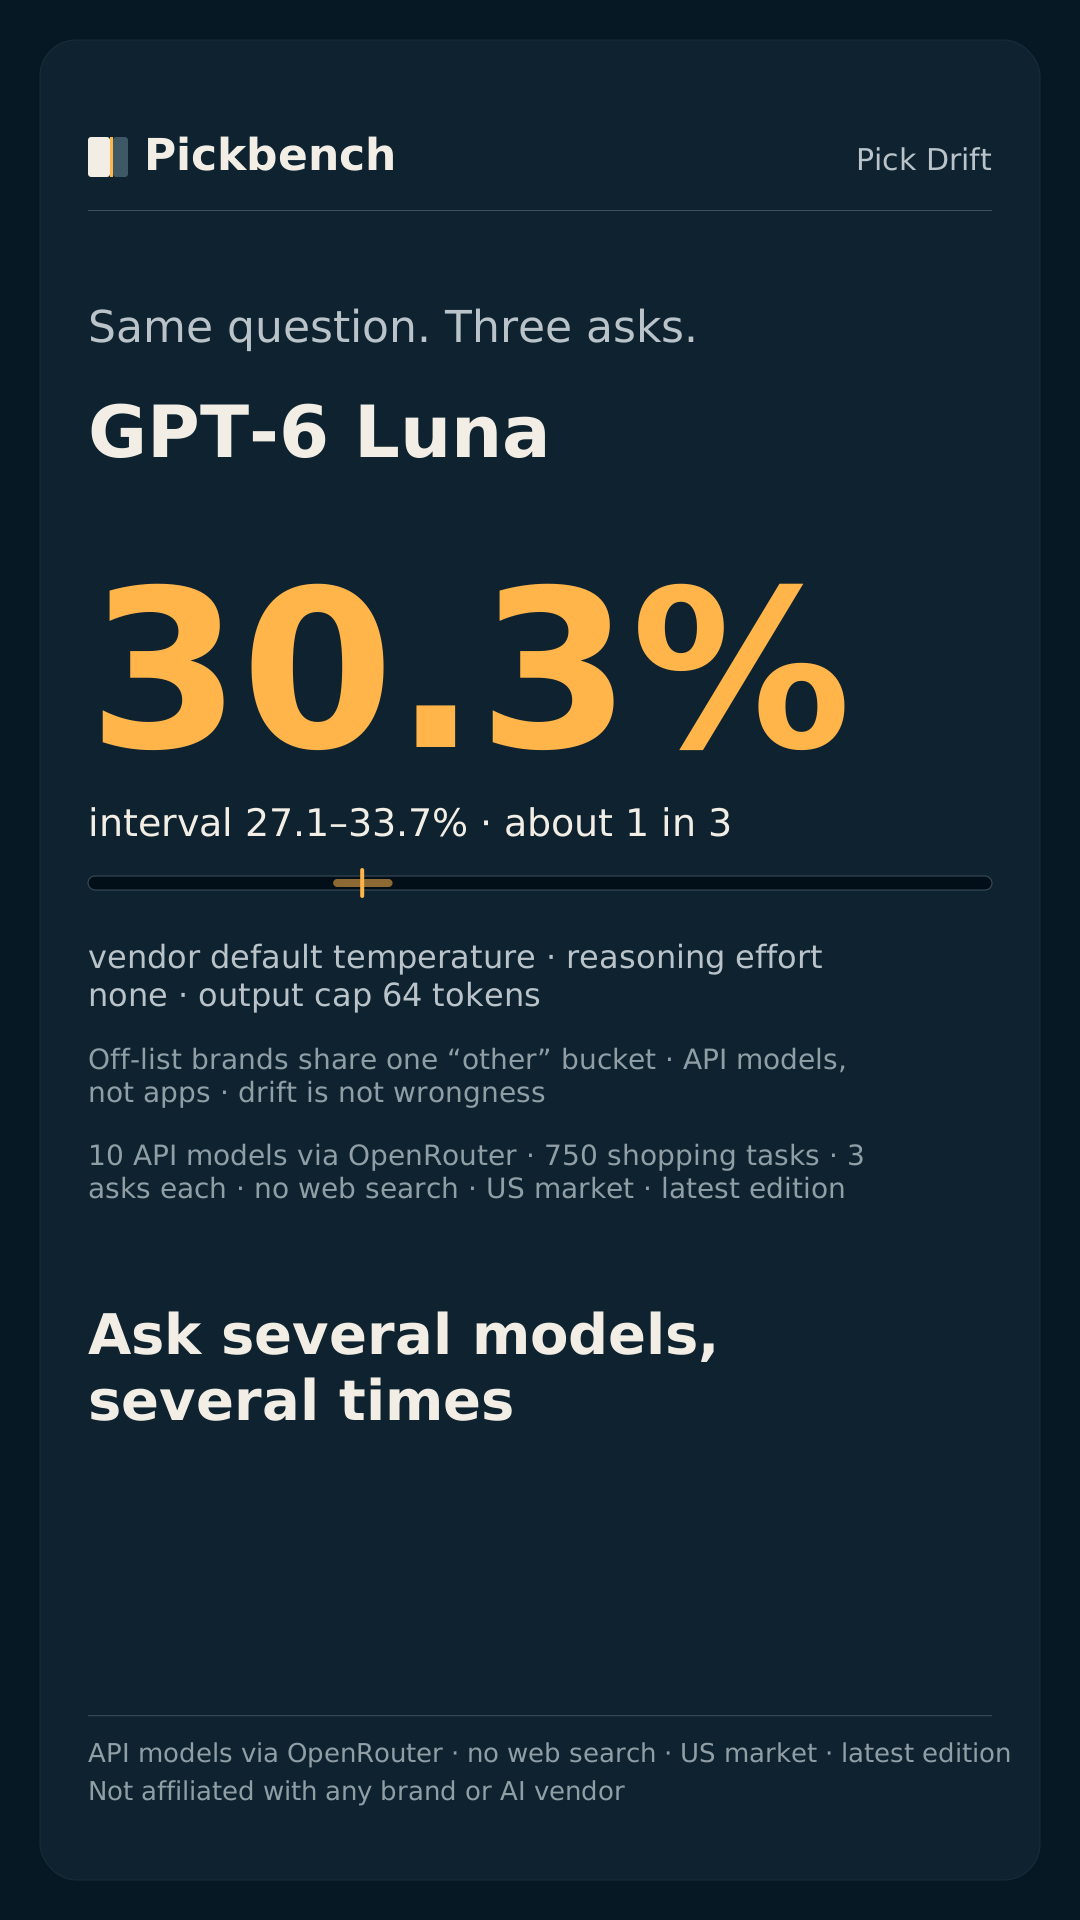
Reasoning effort none · output cap 64 tokens
- Claude Haiku 5.518.7%15.9–21.7%
Details
about 1 in 5 · Two asks differ 13.1% (11.1–15.2%) - GPT-6 Luna30.3%27.1–33.7%
Details
about 1 in 3 · Two asks differ 21.2% (18.9–23.5%)
Temperature 0, set by us
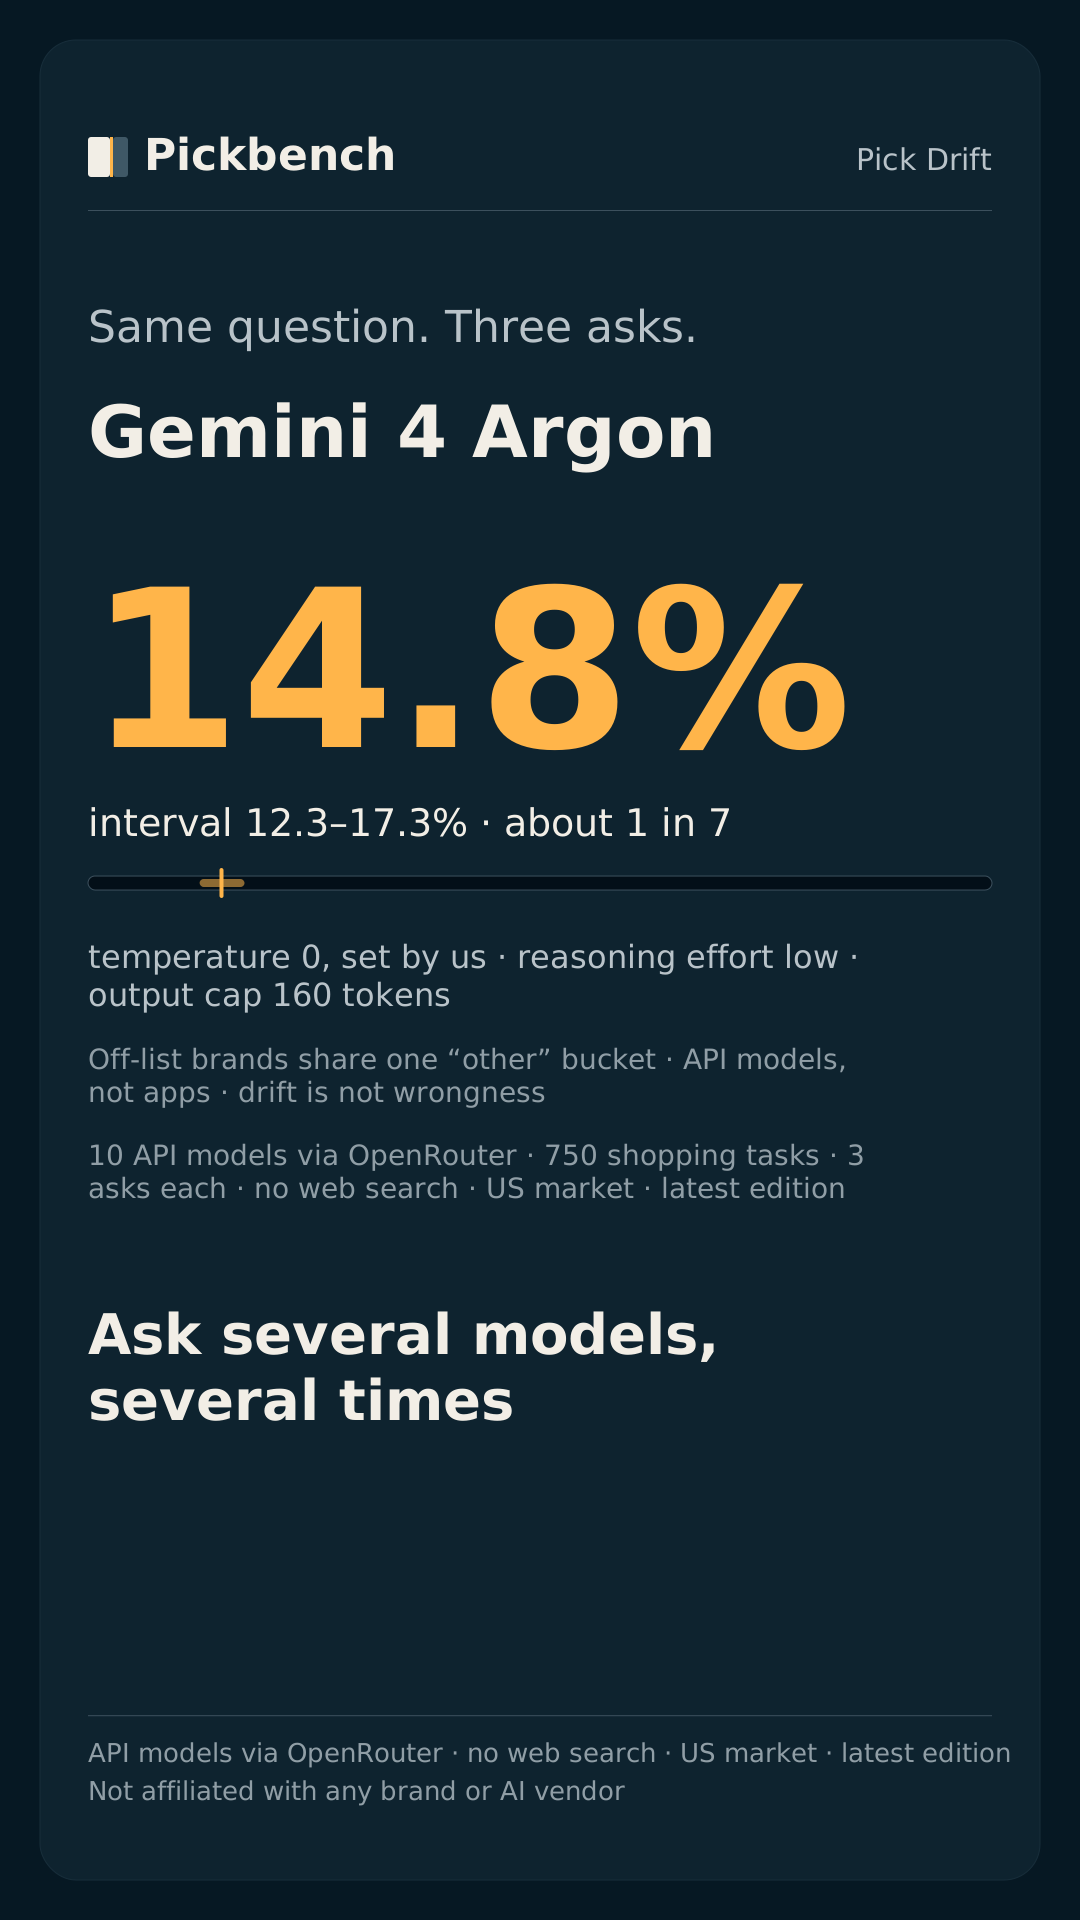
Reasoning effort low · output cap 160 tokens
- Gemini 4 Argon14.8%12.3–17.3%
Details
about 1 in 7 · Two asks differ 10.1% (8.4–11.8%)
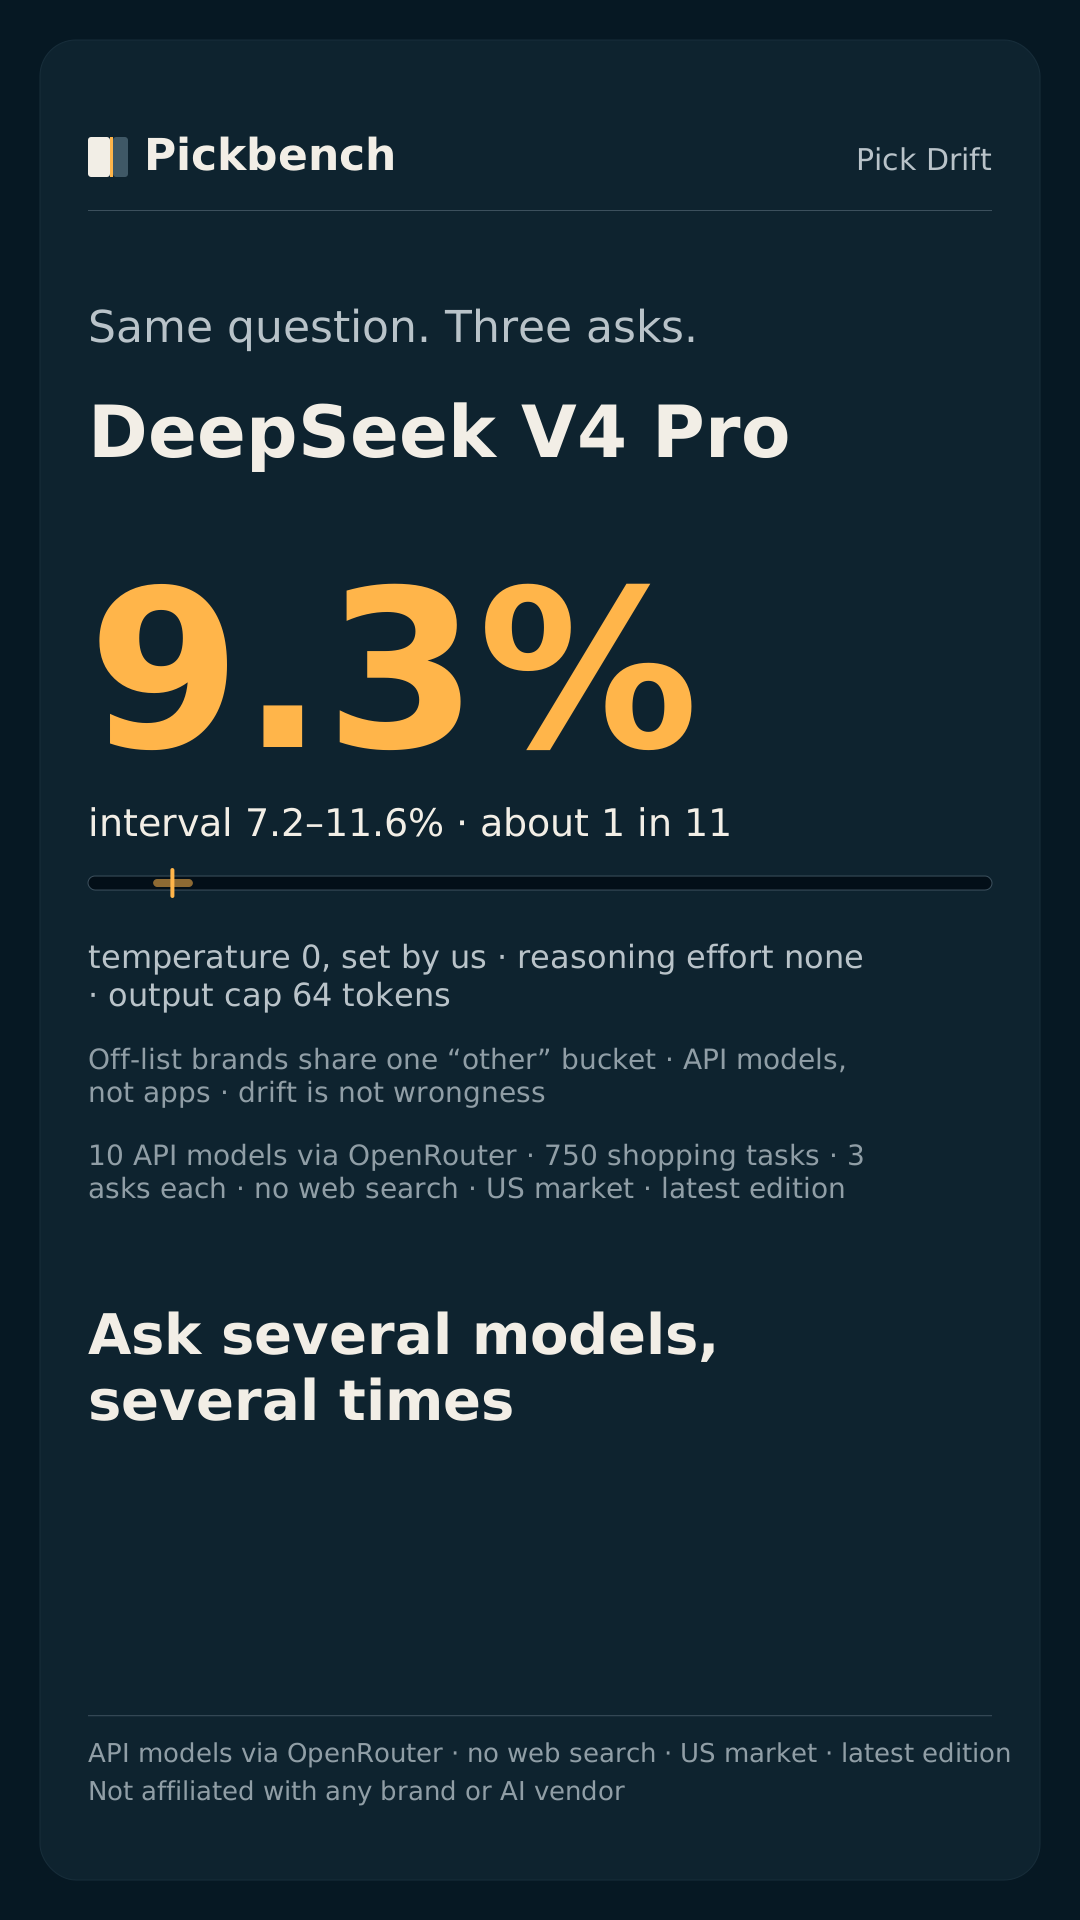
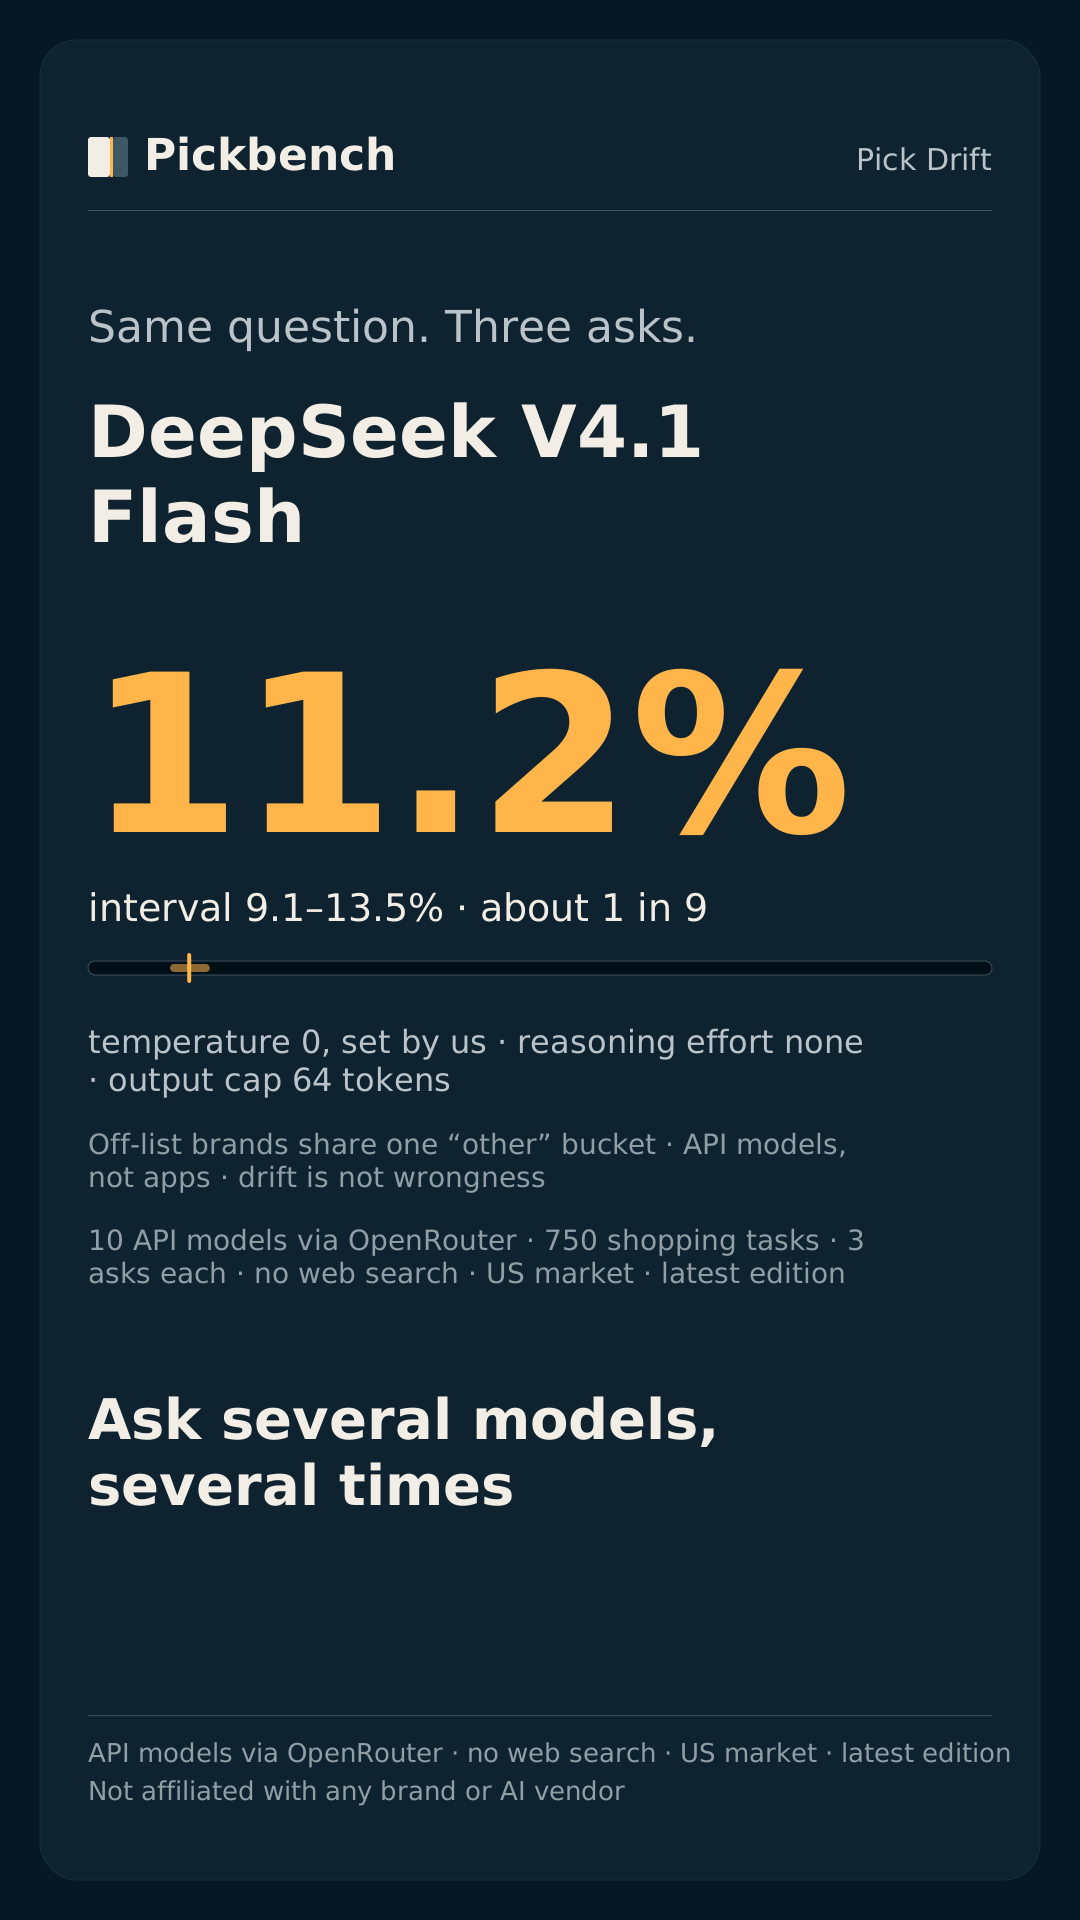
Reasoning effort none · output cap 64 tokens
- DeepSeek V4 Pro9.3%7.2–11.6%
Details
about 1 in 11 · Two asks differ 6.3% (4.9–7.8%) - DeepSeek V4.1 Flash11.2%9.1–13.5%
Details
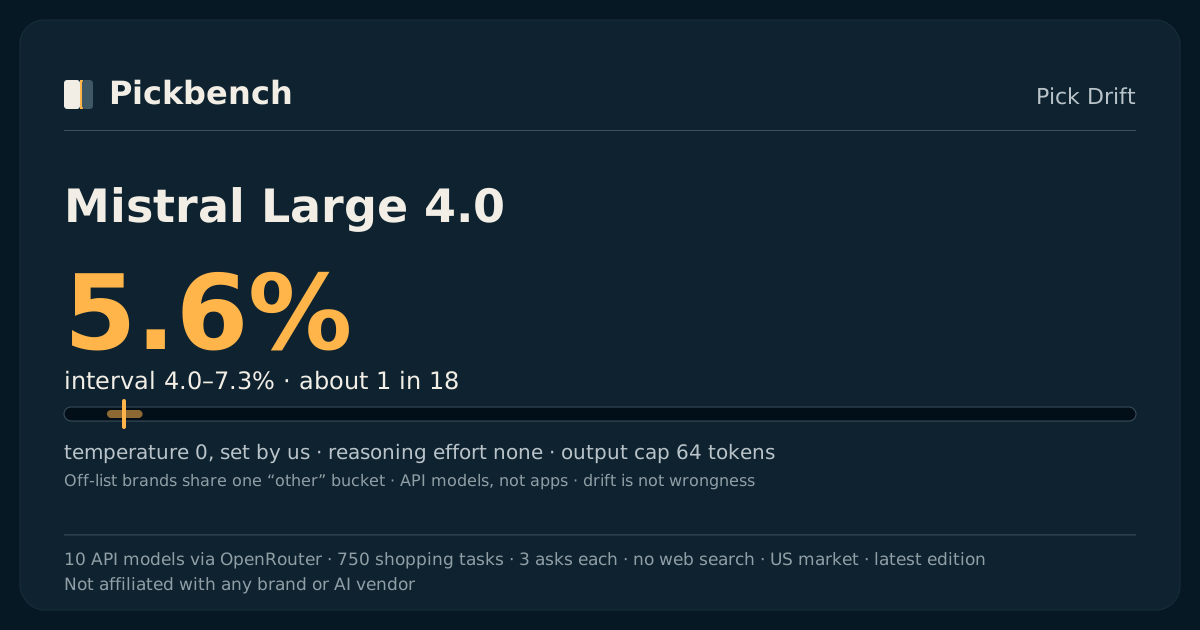
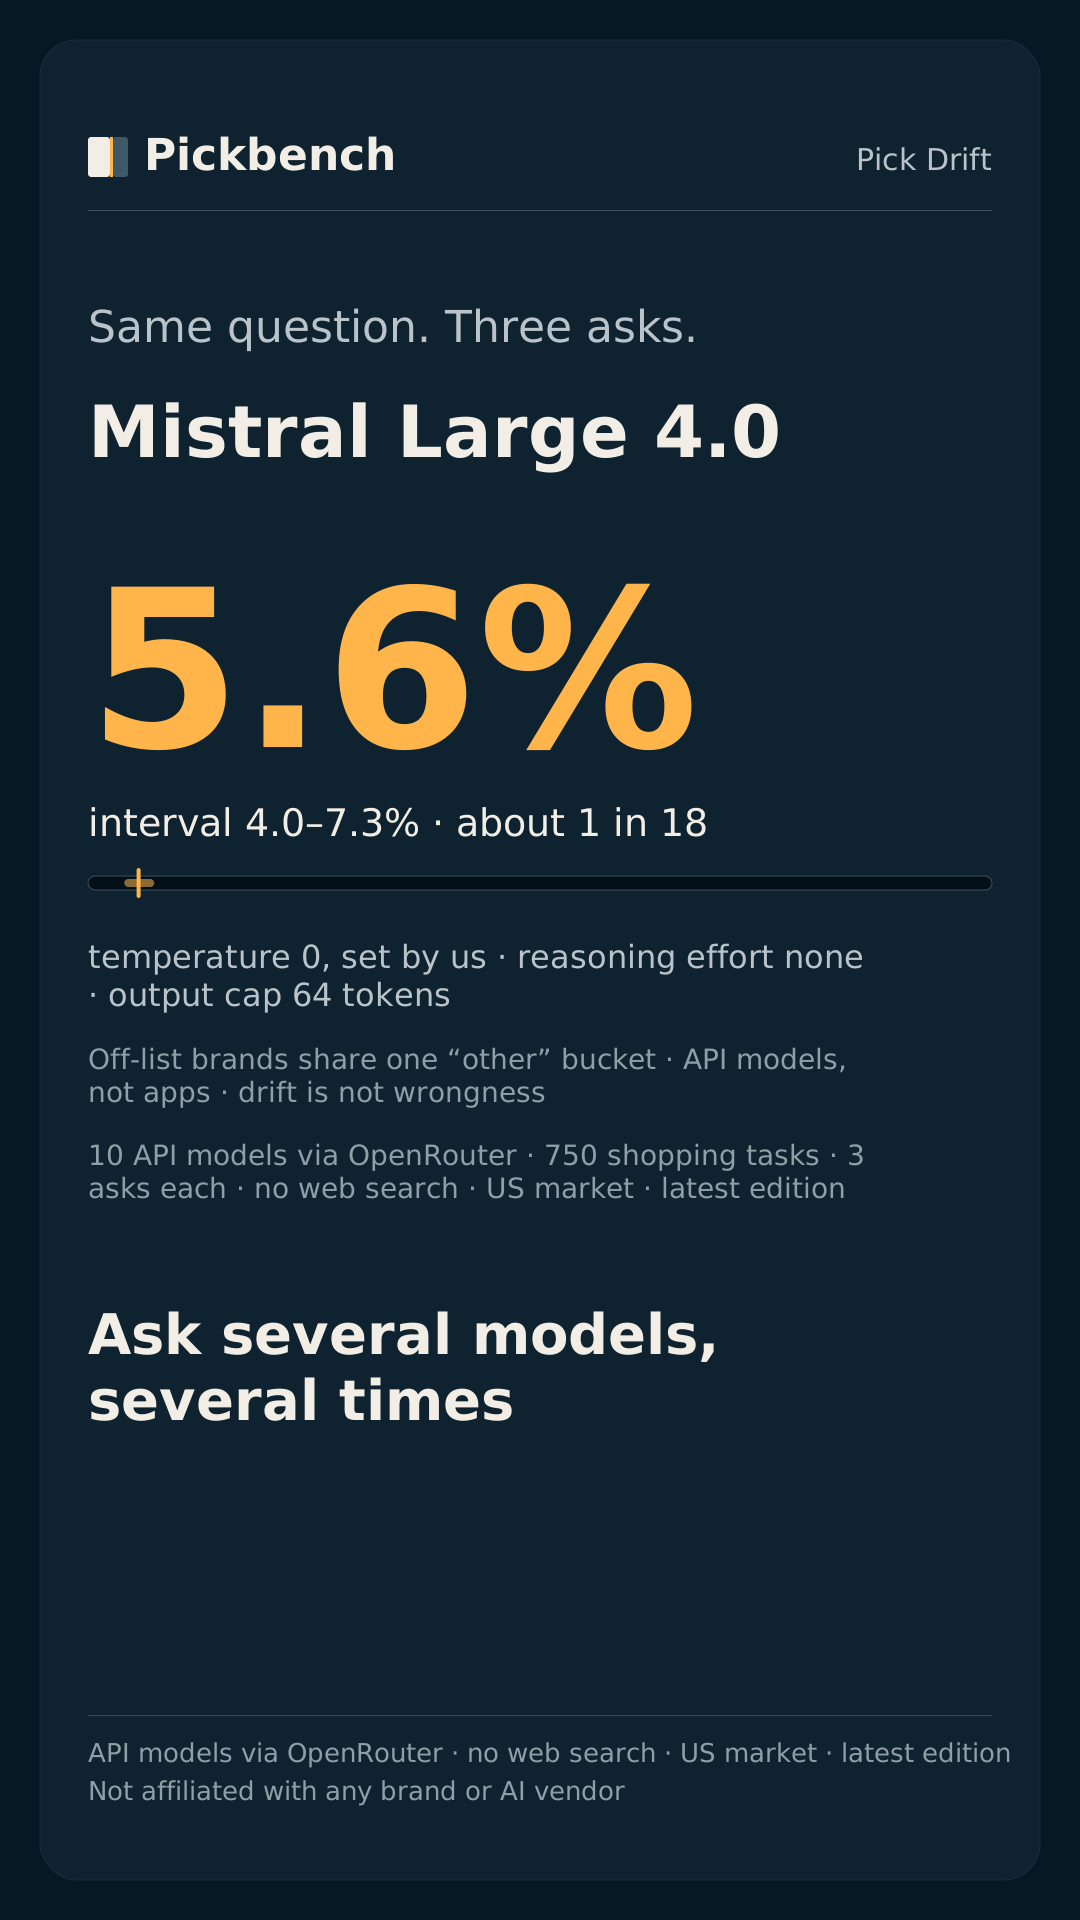
about 1 in 9 · Two asks differ 7.5% (6.1–9.0%) - Mistral Large 4.05.6%4.0–7.3%
Details
about 1 in 18 · Two asks differ 3.7% (2.7–4.9%)
Alphabetical inside each setting. Not a ranking.
10 API models via OpenRouter · 750 shopping tasks · 3 asks each · no web search · US market · latest edition
Comparisons inside one setting
Only between models with equal temperature, effort and output cap, and only where the interval excludes 1.
- Vendor default temperature (reasoning effort low, output cap 160 tokens): Claude Sonnet 5.5 changed its top pick about 1.5 times as often as Claude Opus 5.5 (interval 1.1 to 1.9; post hoc).
- Vendor default temperature (reasoning effort none, output cap 64 tokens): GPT-6 Luna changed its top pick about 1.6 times as often as Claude Haiku 5.5 (interval 1.4 to 2.0; post hoc).
- Vendor default temperature (reasoning effort low, output cap 160 tokens): GPT-6.1 Sol changed its top pick about 1.8 times as often as Claude Opus 5.5 (interval 1.4 to 2.4; post hoc).
- Vendor default temperature (reasoning effort low, output cap 160 tokens): GPT-6.1 Sol changed its top pick about 1.5 times as often as Gemini 3.8 Flash (interval 1.2 to 1.9; post hoc).
- Temperature 0, set by us (reasoning effort none, output cap 64 tokens): DeepSeek V4 Pro changed its top pick about 1.7 times as often as Mistral Large 4.0 (interval 1.2 to 2.5; post hoc).
- Temperature 0, set by us (reasoning effort none, output cap 64 tokens): DeepSeek V4.1 Flash changed its top pick about 2.0 times as often as Mistral Large 4.0 (interval 1.4 to 2.9; post hoc).
Ask ten, not one
One answer from one model is one draw: ask again and the top pick can change. Pickbench asks 10 API models every task 3 times and reports intervals.
The 3-Ask Test
Try it in your own assistant.
- Open a new chat with memory and personalization off.
- Ask one shopping question, such as “Which running shoe brand should I buy?”
- Write down the first brand it names.
- Ask the exact same question in two more new chats.
- Did the first brand change?
Your app test is not our measurement: apps add memory, search and settings we cannot see.
Read this with the number
- Brands outside our reference list share one “other” bucket, so drift is conservative for those tasks.
- It measures API models under our stated conditions (OpenRouter, no web search, our prompt), not consumer apps.
- Drift is not wrongness: a model can alternate between two good options.
- Sampling settings differ per model, so compare only inside one setting group.
Share cards
- Vendor default temperatureCardStory
- Claude Haiku 5.5CardStory
- Claude Opus 5.5CardStory
- Claude Sonnet 5.5CardStory
- Gemini 3.8 FlashCardStory
- GPT-6 LunaCardStory
- GPT-6.1 SolCardStory
- Temperature 0, set by usCardStory
- DeepSeek V4 ProCardStory
- DeepSeek V4.1 FlashCardStory
- Gemini 4 ArgonCardStory
- Mistral Large 4.0CardStory










Method and data
- How Pick Drift is measured
- Benchmark data file (JSON)SHA-256 95079a27c510dd8a73b245f024387a9919c72ae5cb73cae7a6e248c0a6fcbfdf